
Workflow Automation for Warehouses: Handling Hundreds of Approvals per Shift Without Notification Overload
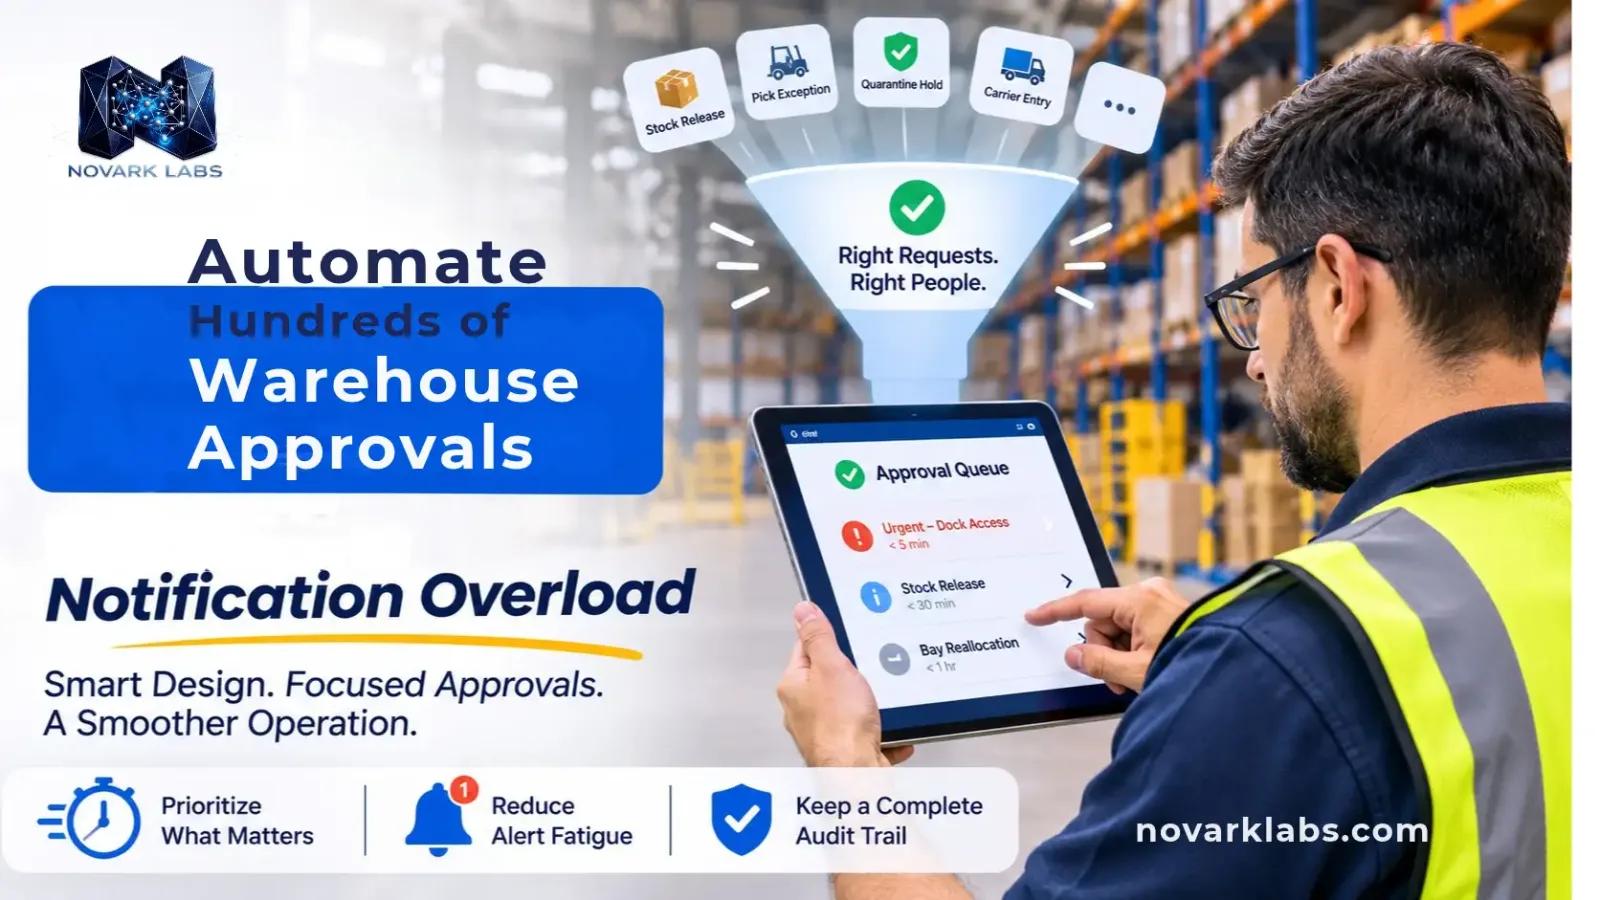
A busy warehouse does not run on big decisions. It runs on thousands of small ones. Can this pallet be released to dispatch? Can that quarantined batch move to a different bay? Can the forklift operator pick from a location that shows a stock discrepancy? Can this carrier's driver through the gate before the booked slot?
Each of these is a minor approval. Taken individually, none is difficult. Taken together, across a single shift, they add up to hundreds of small requests that need a yes, a no, or a "hold on, let me check." That is where most warehouse workflow projects quietly fail.
The usual story goes like this. A team replaces WhatsApp messages and paper sign-offs with a digital approval system. For a week or two it feels like a huge improvement: requests are tracked, decisions are logged, and the audit trail finally exists. Then the volume builds. Supervisors' phones buzz constantly. Approvers start swiping notifications away without reading them. Real urgent requests get buried under routine ones. Within a month, people are back to calling each other, because the "automated" system has become noise.
This article is about avoiding that outcome. It covers why high-volume warehouse approvals are a different design problem from office approvals, how notification overload actually develops, and the practical design principles that let you automate hundreds of approvals per shift while keeping approvers focused, fast and in control.
Why Warehouse Approvals Are a Different Problem
Most workflow tools were designed around office processes: a leave request, a purchase order above a certain value, a contract sign-off. These share a few characteristics. There are not many of them. Each carries real weight. The approver is usually at a desk. And a few hours of delay is tolerable.
Warehouse approvals invert almost every one of those assumptions.
Volume is high and individual value is low. A distribution centre may generate hundreds of authorisations per shift: stock releases, quarantine decisions, bay allocations, returns dispositions, cycle-count adjustments, pick exceptions. Most of them are routine.
Time windows are tight. A dock door booked for a thirty-minute turnaround cannot wait for an email to be noticed. A pick wave held up by an unresolved exception delays every order downstream of it.
Approvers are on their feet. Supervisors and team leaders spend their shifts on the floor, not at a screen. They respond on mobile devices, often one-handed, often while doing something else.
Context is physical. Decisions depend on what is actually in a location, on a pallet or at a door. The approver needs the relevant facts at a glance, not a long form.
Compliance still matters. Even when a decision is trivial, many operations, especially in food, pharmaceutical, hazardous goods and customs-bonded environments, need a complete record of who approved what and when.
The design challenge is therefore unusual: you need speed and volume handling and a full audit trail, without drowning the people who make the decisions. Solving only one of the three is easy. Solving all three takes deliberate design.
How Notification Overload Actually Develops
Notification overload is rarely caused by a single bad decision. It builds through a series of reasonable-looking choices.
Every request becomes a push notification. The simplest way to build an approval system is to send each request to an approver as an alert. At low volume, that works. At hundreds per shift, it creates a constant stream of interruptions.
Everything is treated as equally urgent. If a routine bay reallocation and a quarantine hold on a temperature-sensitive batch arrive in the same way, the approver has no way to tell them apart without opening both. Eventually they stop trying.
One person is the bottleneck. Routing everything to a single named supervisor concentrates the whole queue on one phone. When that person is on a break, in a meeting or dealing with an incident, requests pile up and then arrive in a rush when they return.
Escalations multiply the noise. If a request is not actioned in time, the system escalates it, usually by sending more notifications to more people. When the underlying problem is that the first approver was overloaded, escalation just spreads the overload upward.
Reminders pile on reminders. Repeated nudges for unanswered requests add to the volume rather than reducing it.
The result is a pattern familiar to anyone who has watched alert fatigue in IT operations or healthcare: when too many signals demand attention, people learn to ignore all of them, including the ones that matter.
The Real Cost of Getting This Wrong
Notification overload is not just an annoyance. It has measurable operational consequences.
- Slower cycle times. Approvals that should clear in minutes sit in a queue because the approver cannot separate the urgent from the routine.
- Higher error rates. Approvers who are rushing through a flood of requests are more likely to approve something they should have questioned.
- Workarounds. People revert to phone calls, radio, verbal approvals and messaging apps, which recreates the audit gaps the system was meant to close.
- Lost trust. Once teams decide that the system is slower than the old way, adoption collapses and is very hard to rebuild.
- Approver burnout. Supervisors who spend their shift reacting to alerts have less time to actually supervise.
The goal of good design is therefore not to send fewer approvals through the system. It is to make sure that only the right ones reach a human, in the right form, at the right time.
Principle 1: Not Every Approval Needs a Human
The single most effective way to reduce notification volume is to stop sending requests that do not need a person to decide them.
In most warehouses, a large share of approvals are routine in a way that can be defined by rules. A stock release for a standard SKU, within normal quantity limits, to a verified customer order, with no quality flags, is not really a decision. It is a check that the conditions are met. If they are, the outcome is predictable.
This is where policy-based auto-approval comes in. You define the conditions under which a request is approved automatically, and the system applies them instantly, logging the decision and the rule that triggered it. Only requests that fall outside the rules are routed to a person.
A few examples of approvals that are often good candidates:
- Stock movements between standard locations within the same temperature zone
- Cycle-count adjustments below a defined variance threshold
- Bay or door reallocations within a pre-agreed set of options
- Returns of standard items to stock where inspection checks pass
A few that usually should still go to a person:
- Anything involving a quality hold, quarantine or recall
- Adjustments above a variance or value threshold
- Movements involving hazardous or regulated goods
- Any request that conflicts with another open exception
The key is that auto-approved items are still fully recorded. The audit trail shows the request, the rule applied, the data checked and the timestamp. You lose nothing in compliance terms, but you remove a large part of the volume from the human queue.
A practical way to start is to review a month of past approvals and ask a simple question of each category: how often did the approver say anything other than yes? Where the answer is almost never, the rule is probably already sitting in someone's head, and it can be written down and automated.
Principle 2: Batch Similar Approvals Instead of Sending Them One by One
When requests are similar and arrive in bursts, sending them individually is the worst of both worlds. The approver gets interrupted repeatedly and still has to make the same decision many times.
Intelligent batching groups related requests so they can be reviewed and decided together. Examples include:
- All stock releases for a single outbound wave
- All pick exceptions in one aisle
- All returns processed in the same hour
- All cycle-count adjustments for one zone
The approver sees one grouped item, can scan the contents, approve the lot with a single action, and can still open individual lines to reject or query them. The audit trail still records each line separately, so no per-instance detail is lost.
Batching works best when it is tied to operational rhythms rather than arbitrary time windows. A batch that closes when a wave is released is more useful than one that closes every ten minutes regardless of what is happening on the floor.
One caution: batching should never delay genuinely urgent items. A batch is for routine requests. Anything flagged as time-critical should bypass the batch and go straight through, which leads to the next principle.
Principle 3: Route by Priority, Not by Arrival Order
A queue that treats every request the same will always be dominated by whatever arrives most often, not by whatever matters most.
Priority-based routing assigns each request a level based on the facts of the situation, and treats each level differently. A simple model might use three tiers:
- Critical: affects safety, compliance, a quality hold, or a delivery that is about to miss its window. Delivered immediately with a distinct alert, and escalated quickly if not actioned.
- Time-sensitive: affects throughput in the next hour, such as a blocked wave or a waiting truck. Delivered promptly, with a visible deadline.
- Routine: can wait for the next natural pause. Delivered as part of a digest or batch, with no interruptive alert.
Priority should be assigned by rules, not by the requester. If anyone can mark their own request "urgent," everything becomes urgent within a week. Instead, derive priority from data the system already has: the order's dispatch time, the dock appointment, the SKU's quality status, the customer's service level.
The effect on notifications is significant. Only the critical tier interrupts. The routine tier waits in a quiet queue. Approvers learn quickly that when their phone alerts, it genuinely matters, which restores the trust that overload destroys.
Principle 4: Route to the Right Person, With Delegation Built In
Sending everything to a single named supervisor is simple to configure and painful to live with. Good routing spreads the load sensibly and survives real-world absences.
Route by role and zone, not by individual. Define approvers by what they are responsible for, such as inbound supervisor, chilled zone lead or returns coordinator, and let the system resolve that to whoever is on shift. This keeps requests aligned with the people who actually have the context.
Use shift and presence awareness. If the system knows who is on shift, who is on break and who has handed over, it can avoid sending requests to someone who cannot act on them.
Build in delegation rules. When the primary approver is unavailable, the request should move to a defined delegate automatically, not sit in a queue until someone notices. The delegate chain should be explicit, and each hand-off should be logged.
Balance load where roles overlap. If three team leaders can approve the same type of request, the system can distribute requests among them rather than sending all of them to the first name on the list.
The aim is that no one person's phone carries the whole queue, and that no request is ever waiting on someone who is not there.
Principle 5: Design the Approver Interface for Five-Second Decisions
Even with fewer, better-targeted requests, the way each one is presented determines how quickly it can be handled.
An approver on the warehouse floor does not want a form. They want to understand a request and act on it in a few seconds. Good approval interfaces for this environment tend to share a few features:
- The decision-critical facts first. Item, quantity, location, reason and any flag that makes this request unusual, all visible without scrolling.
- One-tap actions. Approve, reject and query should be single actions, with comments optional rather than mandatory for routine items.
- Large touch targets. People are wearing gloves, holding scanners and moving.
- Clear visual distinction by priority. Colour, ordering and wording should make a critical item look different from a routine one before it is read.
- A grouped inbox rather than a stream of alerts. A single queue the approver can clear in a pass, with counts by priority, is far less stressful than a chain of individual notifications.
- Context on demand. Anyone who wants more detail, such as history, related exceptions or images, can open it, but nobody is forced to.
A useful test: watch a supervisor use the interface on the floor. If they have to stop what they are doing, find a quiet spot and concentrate to process a routine request, the interface is too heavy.
Principle 6: Escalate Without Spamming
Escalation is essential. A request that nobody acts on cannot be allowed to sit indefinitely. But badly designed escalation is one of the biggest sources of notification overload.
A few ways to keep escalation useful rather than noisy:
Tie deadlines to the operational need. A routine request might have a two-hour window; a request blocking a dock door might have ten minutes. Deadlines should reflect what the delay actually costs.
Escalate to a person, not to everyone. Move the request to the next defined level, such as a delegate or the shift manager, rather than copying the whole chain.
Replace repeated reminders with a single clear step. One reminder before the deadline and one escalation at it is more effective than a steady drip of nudges.
Watch the escalation rate itself. If a particular approver or request type escalates constantly, that is a signal that the routing or the rules are wrong, not that people need more reminders.
Keep escalation visible to the requester. Often the person waiting on a decision just wants to know where it is. A clear status, such as "with the zone lead, escalates in eight minutes," prevents the follow-up calls that create their own interruptions.
Principle 7: Keep a Complete Audit Trail for Every Instance
There is a temptation, when reducing volume, to also reduce record-keeping. That is the wrong trade. In a well-designed system, auto-approved, batched and individually decided requests all produce the same quality of record.
For each instance, you should be able to retrieve:
- Who or what made the request, and when
- What data was attached at the time
- Which rule, batch or person decided it
- The decision, the timestamp and any comment
- Any escalation or delegation that occurred
- The outcome, including any write-back to the warehouse management or ERP system
This is what lets you answer a customer audit, a regulator's question or an internal investigation without reconstructing events from memory. It is also what makes it safe to automate aggressively, because you can always show exactly what the system did and why.
The audit trail also becomes a source of improvement. Patterns in the data show which rules are too strict, which approvers are overloaded and which request types generate the most exceptions.
What This Looks Like in Practice: One Shift, Walked Through
Consider a mid-sized distribution centre running a day shift with roughly 400 approval events.
Without any design for volume, every one of those 400 events becomes an alert sent to a supervisor. Even at a few seconds each, that is a constant stream of interruptions, and the critical items are buried in the noise.
Now apply the principles above. These numbers are illustrative, not a benchmark, but they show the shape of the effect:
- A large majority of events, perhaps 60 percent, fall within clear rules and are auto-approved with a full record. The supervisors never see them.
- Of the remainder, a good portion are routine and similar. They are batched by wave, zone or hour, so a team leader reviews a handful of grouped items rather than dozens of individual ones.
- A small number are time-sensitive, delivered promptly with a visible deadline.
- A very small number are critical, such as a quality hold or a blocked dock, and trigger a distinct alert immediately.
The supervisor's phone now alerts a few times per shift for things that genuinely need attention. The rest is a quiet inbox they clear between tasks. Every one of the 400 events still has a full record.
The volume of work has not changed, but the human attention required to handle it has fallen dramatically, and it is now directed at the items that deserve it.
Measuring Whether It Is Working
It helps to track a small set of metrics from the start, so you can see whether the design is working and adjust it.
- Median and 90th-percentile approval time, by priority tier. The median shows typical speed; the 90th percentile shows how bad the slow cases are.
- Share of requests auto-approved. Rising over time, as rules are refined, is usually a good sign, provided exception rates stay stable.
- Notifications per approver per shift. A direct measure of overload. Watch for outliers.
- Escalation rate. High or rising rates point to routing or capacity problems.
- Override and rejection rates on auto-approved categories. If approvers frequently reverse or reject items the rules approve, the rules need tightening.
- Workaround indicators. Calls, radio requests and messaging activity for approvals are a sign that people have stopped trusting the system.
- Approver feedback. A short, regular check-in with supervisors will surface problems that numbers miss.
Rolling Out Without Losing Trust
How you introduce the system matters as much as how it is designed. A few practices help:
Start with a baseline. Before changing anything, measure how many approvals occur, by type, and how long they take today. You cannot show improvement without it.
Begin with the highest-volume, lowest-risk categories. These deliver the biggest reduction in noise and carry the least risk if a rule needs adjustment.
Run in shadow mode first. Let the system propose decisions alongside the existing process for a short period, and compare. This builds confidence in the rules before they are live.
Involve the approvers early. Supervisors know which requests are truly routine and which only look it. Their input makes the rules better and builds ownership.
Review and tune regularly. Rules, thresholds and priorities will need adjusting as the operation changes. Treat the first few months as a tuning period, not a finished project.
Keep a clear route for exceptions. People should always be able to flag that something does not fit the rules and have it handled by a person.
Conclusion
The point of workflow automation in a warehouse is not to move the same flood of requests onto a different channel. It is to make the flood manageable: removing the approvals that never needed a human, grouping the ones that can be decided together, and delivering the rest, in priority order, to the right person in a form they can act on in seconds.
Done well, this gives you what warehouse operations actually need: fast decisions at high volume, supervisors who can focus on the floor instead of their phones, and a complete audit trail for every single instance. Done badly, it gives you a more expensive version of the noise you had before.
If your team is handling hundreds of approvals per shift and the system feels more like a source of interruptions than a help, the answer is rarely more notifications or more reminders. It is almost always better rules, better batching, better routing and a better interface, working together.
Want to see how this could work for your operation? Talk to the Novark Labs team about mapping your highest-volume approvals and designing a workflow that keeps people informed without overwhelming them.
0 comments
Log in to leave a comment.
Be the first to comment.