
Why Operational Software Projects Fail, and a Five-Stage Approach That Avoids It
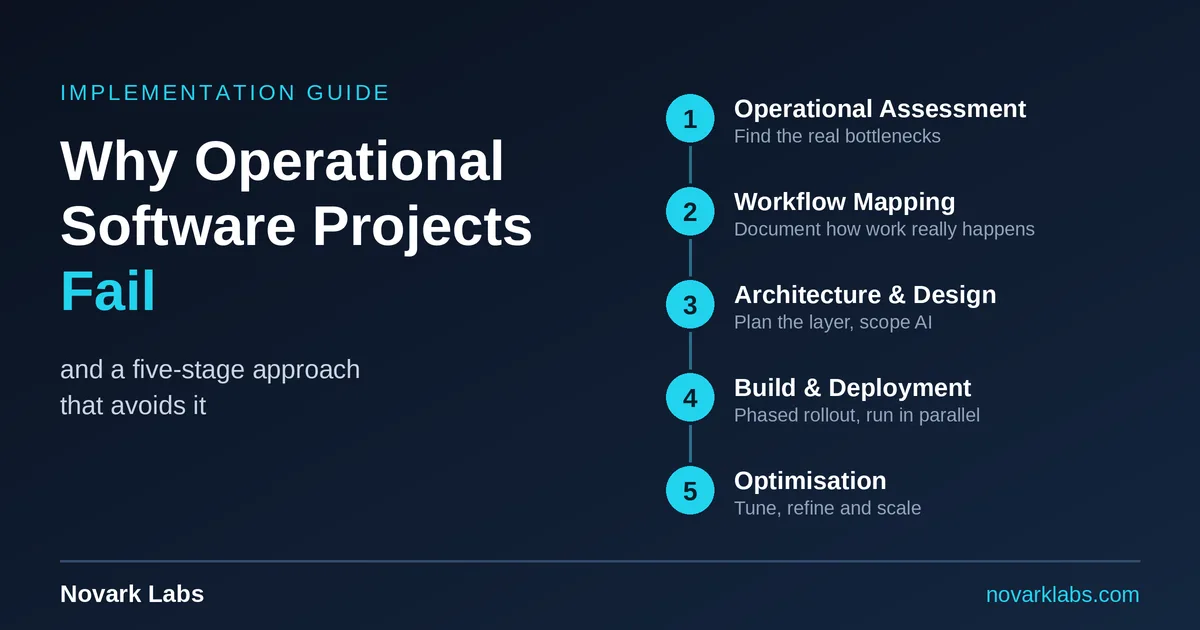
Many operational software projects fail long before anyone writes code. A warehouse, plant or logistics business buys a platform, configures it against the documented procedures and launches it. Months later, supervisors are back on spreadsheets and messaging apps, and the new system sits half-used.
The reasons are rarely technical. They usually come down to how the project was approached. This article explains the most common failure points and walks through a five-stage method, as practiced by Novark Labs, that is designed to avoid them.
Why Operational Software Projects Fail
1. Unclear objectives. If nobody can say which problem the project solves (slow reporting, blind spots between sites, approvals lost in chat), there is nothing to measure success against.
2. Documentation versus reality. Procedures describe how work is supposed to happen. On the floor or in the field, people rely on verbal handovers, informal coordination and workarounds that never made it into a manual. Software built only against the documented process misses all of it.
3. The instinct to replace. When visibility is poor, the reflex is to buy a new system. But the existing ERP, warehouse management system (WMS) or SCADA often works fine for its core job. Replacing it is expensive and disruptive, and it doesn’t fix the real gap, which is the lack of connection between systems.
4. Disconnected stakeholders. If IT chooses the software without input from operations, or the reverse, adoption suffers. The people who must use the tool every shift need a say in how it works.
5. Polishing dashboards too early. A beautiful dashboard fed by delayed or inconsistent data is still wrong, only faster and prettier.
The Core Idea: Layer, Don’t Replace
The approach described by Novark Labs starts from a different premise. Instead of replacing what you run, build an operational intelligence layer above your existing ERP, WMS, SCADA and maintenance systems (CMMS). The layer reads data from those systems without modifying their transactions, then adds live reporting, workflow automation and role-based dashboards on top.
This keeps risk low, because core systems keep running as they always have. It also shortens time to value, since you are building on top of data that already exists. For background on the concept itself, see this guide to operational intelligence.
The Five Stages
Stage 1: Operational Assessment
Before any design or build, the first stage identifies reporting bottlenecks, workflow delays and visibility gaps.
What happens:
- Interviews with managers, supervisors and floor or field teams
- A review of current workflows
- An inventory of existing systems, including ERP, WMS, SCADA, CMMS, spreadsheets and manual logs
- Analysis of reporting cycles and how stale the data is by the time it arrives
What you get: an operational findings document, a visibility gap assessment and a high-level workflow map.
Client involvement is highest here, because the quality of everything that follows depends on how well the operation is understood.
Stage 2: Workflow Mapping
This stage documents how work actually happens, not how the procedure says it should. That includes informal coordination, verbal handovers and the workarounds people use every day.
What happens:
- Mapping approval chains from start to finish
- Following shift and daily reporting loops
- Tracing dispatch, yard and field flows
What you get: detailed workflow diagrams, bottlenecks ranked by operational and cost impact, and a prioritized list of automation opportunities.
Operators and supervisors take center stage, since they hold the knowledge that no manual captures. Ranking bottlenecks by impact also keeps the project focused on the problems worth solving first.
Stage 3: System Architecture and Solution Design
With the real workflows understood, a blueprint is created for a non-disruptive visibility and automation layer.
What happens:
- Mapping data sources to an integration layer
- Structuring automation logic for approvals, escalations and handovers
- Defining reporting layers and KPI rules
- Designing real-time dashboards and role-based views
- Deciding where AI adds value and where simple rules are enough
What you get: an architecture blueprint, a phased roadmap, an integration plan and an AI scope document.
The AI decision matters. A simple threshold alert, such as “notify the supervisor when stock drops below a level”, often does the job without any machine learning. AI components such as anomaly detection are scoped only where the data justifies them.
Stage 4: Build and Deployment
The system is built to the blueprint and rolled out in phases. Importantly, it runs alongside existing manual processes, with no forced cutover.
What happens:
- Building connectors to ERP, WMS, SCADA and CMMS using APIs, database connections or scheduled data exchange
- Building automation rules and approval routing
- Building dashboards on live data
- Configuring triggers, thresholds and alert logic
- Running in parallel with current processes until accuracy is proven
What you get: a working integration and automation layer, tested workflow logic, live dashboards and alert thresholds calibrated against your real data.
Parallel running is the key safeguard. Teams can compare the new outputs with the old ones, build trust and catch errors before anyone depends on the system.
Stage 5: Optimisation and Continuous Improvement
Deployment isn’t the finish line. Once the system is live, it needs tuning based on real performance.
What happens:
- Reviewing KPI thresholds and calculations
- Refining workflows from user feedback
- Tuning alerts to reduce false positives
- Improving reports and dashboards
- Surfacing new insights from accumulated history
What you get: an ongoing optimisation roadmap, periodic performance reviews and a strategy for scaling to additional sites or workflows.
False positives deserve special attention. If alerts fire too often, people learn to ignore them, and the system loses its value.
Can This Be Done Remotely?
Yes, the model described is designed for remote delivery. Assessment interviews, workflow walkthroughs and design reviews run through video sessions, screen sharing and document review. For field and inspection systems, on-site coordinators and supervisors test under real conditions while the engineering team monitors and refines remotely. This makes the approach practical for businesses spread across several cities or regions.
What a Good Integration Layer Needs to Support
Operational environments are rarely uniform, so the layer has to cope with a mix of old and new technology. Typical requirements include:
- ERP connectivity, such as SAP, Oracle, NetSuite, Microsoft Dynamics and Pronto
- WMS connectivity, including commercial and custom systems
- SCADA and historian data, through protocols such as OPC-UA, MQTT and Modbus
- CMMS connectivity, for work orders and equipment data
- Legacy sources, including SQL and Access databases, spreadsheets and manual logs
- Field devices and offline-capable mobile apps, for locations with poor connectivity
- Flexible hosting, including cloud or on-premise options where data sovereignty matters
If a vendor can’t explain how it will connect to your specific systems, treat that as a warning sign.
What a Responsible Approach Doesn’t Do
A useful test of any methodology is what it refuses to do. According to Novark Labs, a sound approach avoids:
- Replacing functioning ERP, WMS or SCADA systems unnecessarily
- Forcing migrations that halt operations
- Automating or adding AI without understanding the physical workflow
- Adding AI for show when rules work better
- Tuning dashboards before fixing the underlying workflow and data delays
How Long Does It Take?
Timelines depend on scope. Novark’s implementation page says a focused pilot covering one or two workflows typically takes 4 to 8 weeks, while a full multi-workflow system with ERP, WMS or SCADA integration takes 8 to 16 weeks. The firm’s homepage mentions 6 to 12 weeks for workflow automation, so expect the exact figure to be scoped during assessment.
Starting small is usually wise. A pilot at one site or with one or two workflows proves the value, exposes integration surprises early and builds internal support before a wider rollout.
Questions to Ask Before You Start
Whether you work with a specialist or build in-house, these questions improve your odds:
- What specific problem are we solving, and how will we measure it?
- Who on the operations side will help map the real workflows?
- Which existing systems must we connect to, and what data do they expose?
- Can we run the new system in parallel before relying on it?
- Where is AI genuinely needed, and where would a simple rule do?
- Who will tune and maintain the system after launch?
Final Thoughts
Operational software succeeds when it is built around how an operation really runs, connected to the systems that already hold the data, and improved after launch. The five stages above (assess, map, design, build in phases, then optimise) give a structure that keeps risk low and adoption high.
If you’re weighing a similar project, start by writing down your three slowest reports or approval chains. Those are usually the best candidates for a pilot. To see how this method is applied in practice, you can read the full implementation approach, browse the available solutions, or request an operational assessment from Novark Labs.
0 comments
Log in to leave a comment.
Be the first to comment.