
Why Operational Software Fails Before It's Built (and How to Engineer Around It)
A practical look at how operational intelligence systems should be implemented in logistics, warehousing, manufacturing and mining.
Every operations leader has seen it. A new platform is selected, a dashboard goes live, and for a few weeks everyone is optimistic. Then the numbers stop matching the floor, the supervisors go back to their spreadsheets, and the expensive system becomes something people open only when someone senior asks.
The usual explanation is that the technology wasn't good enough. In most cases, that isn't the real problem. The real problem is the order of work: the software was configured against how the operation is documented, not how it actually runs.
This article explains why that gap causes so many failures, and what a better implementation approach looks like.
The Gap Between the SOP and the Shift
Every site has two versions of its operation.
The first is the one on paper: standard operating procedures, process maps and reporting templates. The second is the one that runs every shift: verbal handovers, informal workarounds, a spreadsheet that only one supervisor fully understands, and decisions made on experience rather than on a screen.
Most software projects are built against the first version. Most operations run on the second. When the two meet, the configuration breaks, the data stops being trusted, and adoption quietly collapses.
The lesson is simple: if you don't understand how work really happens, you can't build a system that supports it.
Start With the Operation, Not the Platform
A more reliable approach reverses the usual sequence. Instead of choosing a platform and then fitting the operation to it, the work begins with the operation and lets the design follow. Here is what that looks like in five stages.
1. Operational Assessment
The first step is listening. That means interviewing managers, supervisors and floor teams, and building an inventory of every system, report and spreadsheet in use. The goal is to understand where information is created, where it gets stuck, and where decisions are delayed.
This stage often surfaces problems that were never on the original brief, such as reports that take half a day to compile, or data that exists in three places with three different answers.
2. Workflow Mapping
Next, the real workflows are documented: who does what, in what order, with which tools, and where the handoffs happen. This is not a copy of the SOP. It is a record of how work is actually done, including the unofficial steps that keep things moving.
This map becomes the foundation for every design decision that follows.
3. Architecture and Design
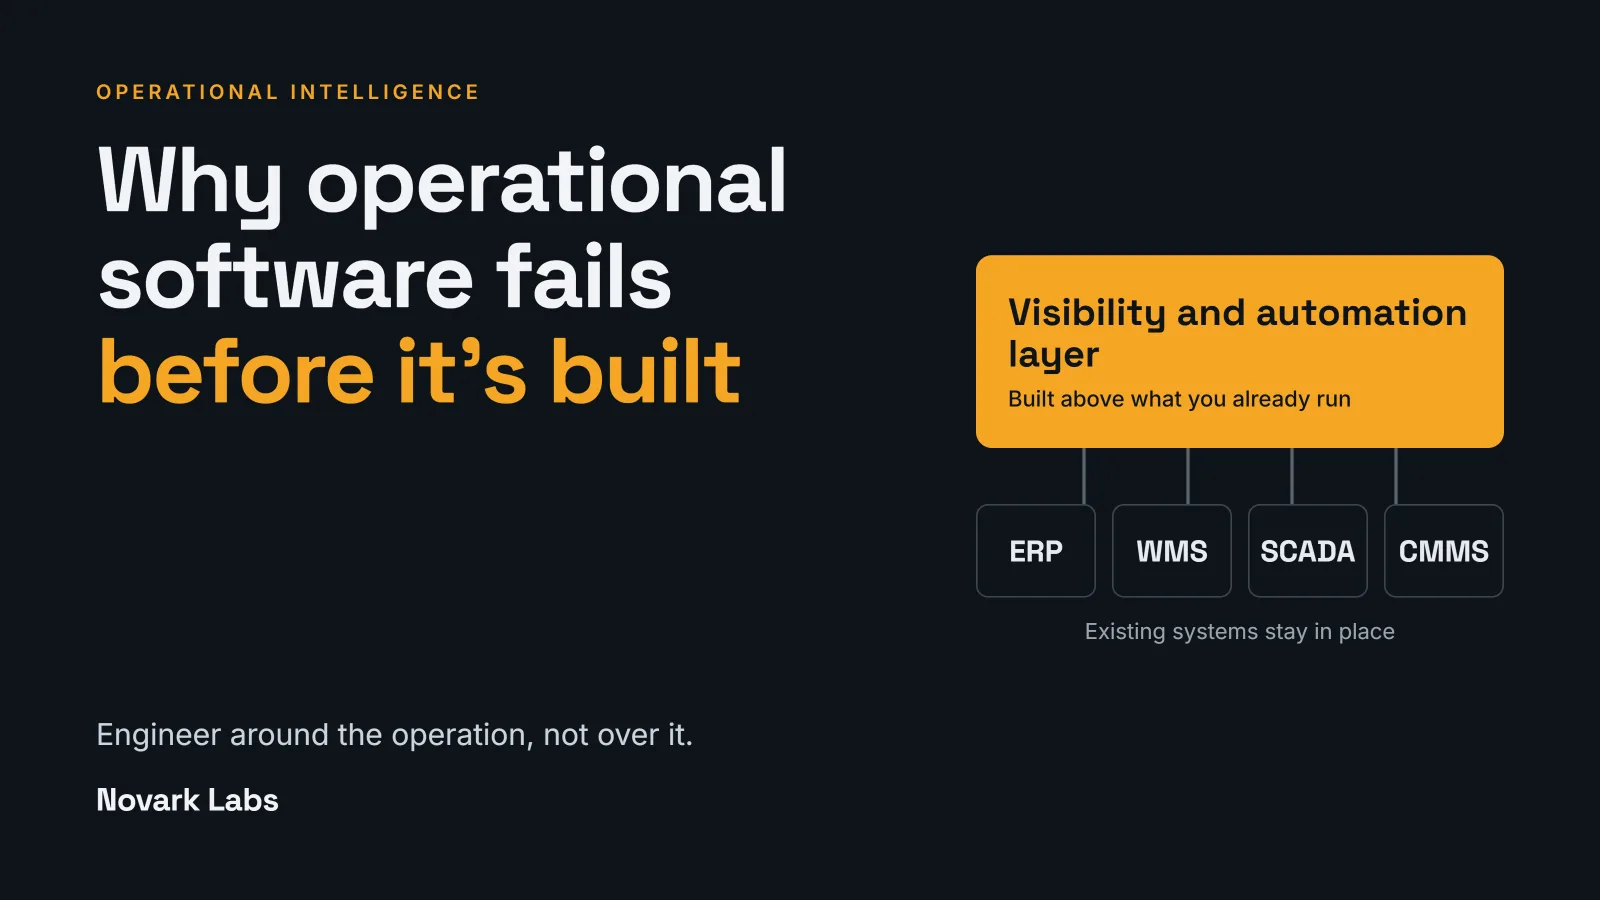
With a clear picture of the operation, the design can begin. A key principle at this stage is to build a visibility and automation layer above the systems you already have, rather than replacing them.
In practice, that means connecting to existing ERP, WMS, SCADA and CMMS platforms and bringing their data together, so teams get one reliable view without a disruptive migration. Systems that already work keep working.
4. Build and Deployment
Rollout happens in phases. Critically, the new system runs in parallel with the current process until its accuracy has been proven against real operations. There is no forced cutover, and no day when the site has to trust something unproven.
This builds confidence in a way no demo can. When supervisors see the new numbers match what they know to be true, adoption follows naturally.
5. Continuous Optimisation
Operations change, so the system has to change with them. After go-live, thresholds, workflows and alerts are refined against real operating data. The first version is rarely the final one, and a good implementation expects that.
Be Honest About What Technology Should and Shouldn't Do
A trustworthy approach is as clear about what it won't do as about what it will. Three principles stand out.
Don't replace what already works. If an existing system does its job, the better move is to connect to it, not rip it out. Rip-and-replace projects carry real operational risk, and they can halt the very work they were meant to improve.
Don't force a disruptive migration. Operations can't pause while a new platform is installed. Any plan that requires stopping the site to change systems deserves skepticism.
Don't add AI for its own sake. AI is valuable when the data supports it, such as spotting patterns in monitoring data that a fixed threshold would miss. But when a simple rule-based alert is the better engineering decision, that is what should be built. Sometimes the most responsible answer is the simpler one.
What Realistic Timelines Look Like
Operational projects often fail on expectations as much as on technology. A focused pilot, built around one workflow or one reporting problem, can typically be live in around 4 to 8 weeks. A fuller system that spans several workflows and data sources more often takes 8 to 16 weeks.
Starting with a pilot has a second benefit: it proves value on a small scale, which makes it easier to secure buy-in for the larger rollout.
Signs Your Operation Needs a Different Approach
You may be a good candidate for an operations-first approach if:
- Reports are produced manually and arrive too late to act on.
- Systems don't talk to each other, so teams reconcile data by hand.
- Dashboards exist, but nobody trusts them enough to make decisions from them.
- Past software projects stalled after go-live.
- Key knowledge lives in people's heads or in personal spreadsheets.
If several of these sound familiar, the issue probably isn't the tools. It's how they were introduced.
A Note on Delivery
Operational intelligence work doesn't always need a team on site. Remote delivery is well suited to this kind of project, as long as the early discovery work is done properly. Novark Labs delivers remotely for operations across Perth, Adelaide, Dammam and Al Khobar, across logistics, warehousing, manufacturing and mining.
The Takeaway
Operational software fails when it is built for the operation on paper. It succeeds when it is engineered around the operation as it really runs: understood first, designed second, proven in parallel, and refined over time.
The principle is easy to state and harder to follow: engineer around the operation, not over it.
To see how this approach works in practice, read the full implementation approach at Novark Labs.
0 comments
Log in to leave a comment.
Be the first to comment.