
Why Most Generative AI Projects Stall — And What the Team Behind the Ones That Ship Looks Like
Generative AI has produced more abandoned proof-of-concepts than almost any technology wave before it. The entry barrier is genuinely low — a developer with a few days of time can build a working chatbot or content generation demo using the available APIs and open-source tooling. The gap between that demo and something that runs reliably in production, integrates into real business workflows, scales under actual user load, and continues to perform accurately over time is where the majority of enterprise generative AI initiatives stall.
The technology is rarely the limiting factor. The team is.
Understanding what a generative AI project actually needs — in terms of roles, skills, and the specific combination of people — is the most useful starting point for any organization that wants to move past the demo stage.
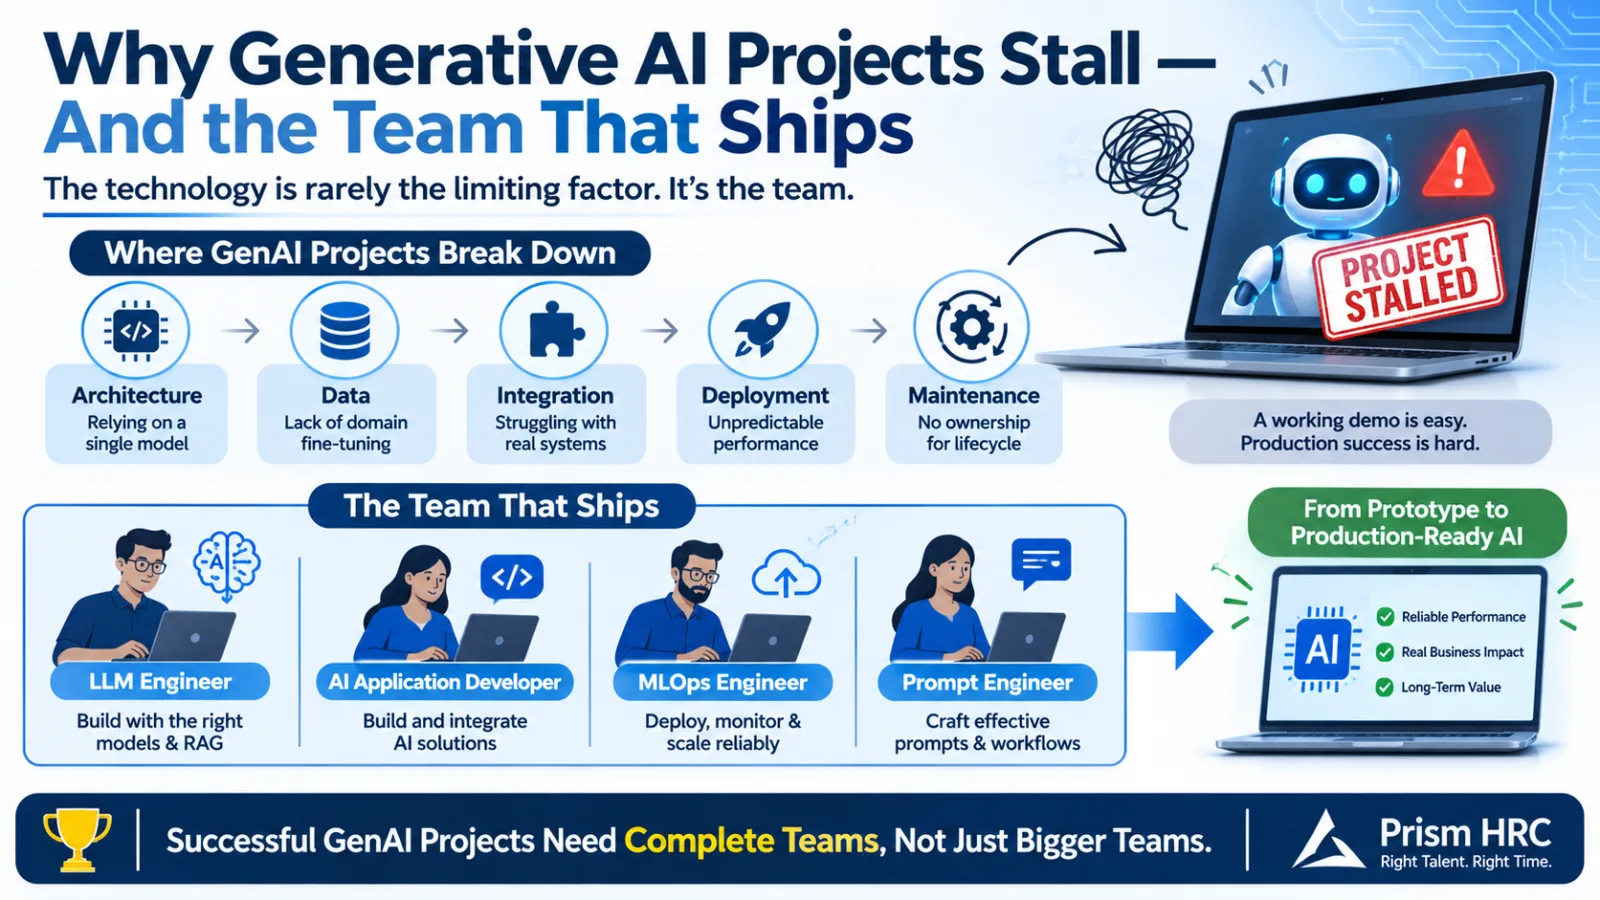
Where GenAI Projects Break Down
Before mapping the team, it is worth being specific about where the failures occur — because each failure point maps to a gap in a particular type of expertise.
At the architecture stage: The team builds around a single model or API without thinking about what happens when that model's behavior changes, costs increase, or a better option becomes available. This is an LLM engineering and architecture gap.
At the data stage: The model performs well on generic inputs but poorly on the company's actual domain — industry-specific language, proprietary terminology, internal process logic. This is a fine-tuning and RAG (Retrieval-Augmented Generation) gap.
At the integration stage: The AI component works in isolation but breaks when connected to real systems — existing databases, APIs, authentication layers, downstream workflows. This is an AI developer and integration engineering gap.
At the deployment stage: The model works in testing but behaves unpredictably in production — inconsistent outputs, latency issues, context window management failures, hallucinations that appear only under specific input patterns. This is an MLOps and AI infrastructure gap.
At the maintenance stage: The model was deployed but no one owns monitoring, retraining triggers, or output quality evaluation. The system drifts quietly and nobody notices until users stop using it. This is an ongoing ownership and ML lifecycle management gap.
The Team That Ships
Generative AI projects that reach and remain in production reliably share a recognizable team structure. It is not always large — a team of four or five genuinely skilled people can deliver production-grade GenAI applications for most enterprise use cases. But each of the following roles needs to be filled, either by a dedicated person or by someone with genuine depth in multiple adjacent areas.
LLM Engineer — The core of a GenAI team. Works with large language models at the technical level: selecting appropriate models for specific use cases, implementing fine-tuning where needed, building RAG pipelines using vector databases like Pinecone or FAISS, managing prompt templates and context windows, and evaluating model outputs systematically. Proficiency in LangChain, LlamaIndex, and the OpenAI and Hugging Face ecosystems is standard. This is the role that requires the most current knowledge — the LLM landscape is moving fast and engineers who were current twelve months ago may not be current today.
AI Application Developer — Builds the application layer around the AI components: APIs, user interfaces, integration with existing systems, data pipelines, and the infrastructure that makes the model accessible to users. Strong software engineering fundamentals alongside AI familiarity. Typically working in Python with frameworks that vary by deployment target.
MLOps or AI Infrastructure Engineer — The person who makes the AI system reliable. CI/CD pipelines for model deployment, monitoring systems that catch output degradation, containerization and orchestration, cost management for inference at scale, and the operational scaffolding that keeps the whole system running. Without this role, generative AI applications work in staging and misbehave in production.
Prompt Engineer or AI Product Specialist — Often underestimated. The quality of a GenAI application's outputs depends significantly on how the model is instructed — system prompts, few-shot examples, output format constraints, and the logic that governs how user inputs are processed before reaching the model. This requires both technical understanding and strong domain knowledge about what good output actually looks like for the specific use case.
What Hiring for These Roles Actually Requires
The challenge with hiring generative AI engineers is that the field is moving faster than most candidate evaluations. Someone who was genuinely expert in GPT-3 era workflows may not have kept pace with the shift to GPT-4, multimodal models, and the current generation of open-source LLMs like Llama and Mistral. Evaluating genuine current competence — not just familiarity with concepts — requires assessment that goes beyond resume review.
This is the specific context where working with a specialist partner to hire Generative AI engineers makes the most practical difference. Prism HRC screens for applied experience — not framework familiarity in theory, but demonstrable work building and deploying systems using LangChain, LlamaIndex, OpenAI APIs, RAG pipelines, and vector databases in real production contexts. Candidates delivered within 72 hours of requirement confirmation reflect a pre-screened pipeline that is actively maintained within the generative AI community — not sourced fresh for each request.
The case study of an eCommerce company filling AI/ML Engineer, Generative AI Developer, and Data Scientist positions within the expected timeline — improving personalization and automating content workflows — reflects what correctly structured, quickly executed hiring produces when the candidate quality is right from the start.
The Composition Question
One of the most consistently useful questions to ask before starting a GenAI hiring process is: what does the team currently have, and what is it missing?
An organization with strong ML engineers but no MLOps capability will build models it cannot reliably deploy. One with strong application developers but no LLM engineering depth will build integrations that do not work well with the underlying models. One with generative AI expertise but no domain knowledge will build systems that technically function but generate outputs that the business cannot use.
The gap analysis almost always points to the same conclusion: generative AI projects succeed when the team covers the full stack from model selection through production deployment and ongoing maintenance — and stall when any of those layers is missing.
The generative AI products that are actually running in production today were not built by larger teams. They were built by more complete ones.
Author Bio
Nikhil Vaidya is the CEO of Prism HRC, a leading recruitment services company in India. Nikhil's expertise in talent acquisition and has been instrumental in connecting hundreds of top-notch clients with exceptional IT talent over the last 15 years.
0 comments
Log in to leave a comment.
Be the first to comment.