
What You Need to Know About RAG vs Fine-Tuning in AI Model Customization
A Quiet Revolution in AI: The Diverging Paths of RAG and Fine-Tuning
Imagine a vast library crammed with countless volumes, each filled with knowledge waiting to be summoned at a moment’s notice. Now envision two scholars poised at its gates: one trained to memorize and recite passages verbatim, and the other skilled at navigating the labyrinth to find the most relevant book in real time. This metaphor sketches the essence of the ongoing debate between Retrieval-Augmented Generation (RAG) and fine-tuning in artificial intelligence.
The distinction might seem subtle at first, but it defines how AI models learn, adapt, and respond to new information. RAG, emerging prominently in the past few years, marries large language models with external knowledge retrieval, enabling dynamic access to fresh data. Fine-tuning, by contrast, is the traditional craft of molding a model's internal parameters to embed specialized knowledge directly into its neural fabric.
As AI's role deepens across industries—from healthcare diagnostics to legal research, and beyond—the choice between RAG and fine-tuning carries consequences that ripple through performance, cost, scalability, and even ethical considerations. This article charts the contours of both approaches, weaving through their technical roots, contemporary applications in 2026, and the critical trade-offs that shape how organizations tailor AI models to their unique demands.
Tracing the Origins: How RAG and Fine-Tuning Found Their Footing
The history of AI model customization is a story of incremental steps punctuated by sudden leaps. Fine-tuning traces back to the earliest days of neural networks, where models like BERT and GPT demonstrated remarkable adaptability when pretrained on massive datasets and then refined on task-specific corpora.
This process, essentially retraining a model on a smaller, domain-specific dataset, embeds specialized knowledge directly into millions or billions of parameters. But as models ballooned in size—GPT-3 reaching 175 billion parameters, and beyond—fine-tuning grew increasingly resource-intensive and inflexible. Any update or inclusion of new knowledge required retraining or expensive parameter-efficient techniques.
Retrieval-Augmented Generation, on the other hand, emerged as a response to these limitations. First spotlighted in research papers circa 2020, RAG architectures combine pretrained language models with retrieval systems that query external knowledge bases on the fly. Instead of internalizing every fact, the model learns to fetch relevant documents or snippets from a live datastore, integrating this information into its generation process.
By 2026, RAG has evolved from a research curiosity to a practical tool, especially in domains where knowledge is volatile and expansive—news, scientific literature, or regulatory compliance. Meanwhile, fine-tuning remains favored when organizations require deeply ingrained domain expertise with strict latency or privacy constraints.
RAG vs Fine-Tuning: A Technical and Practical Comparison
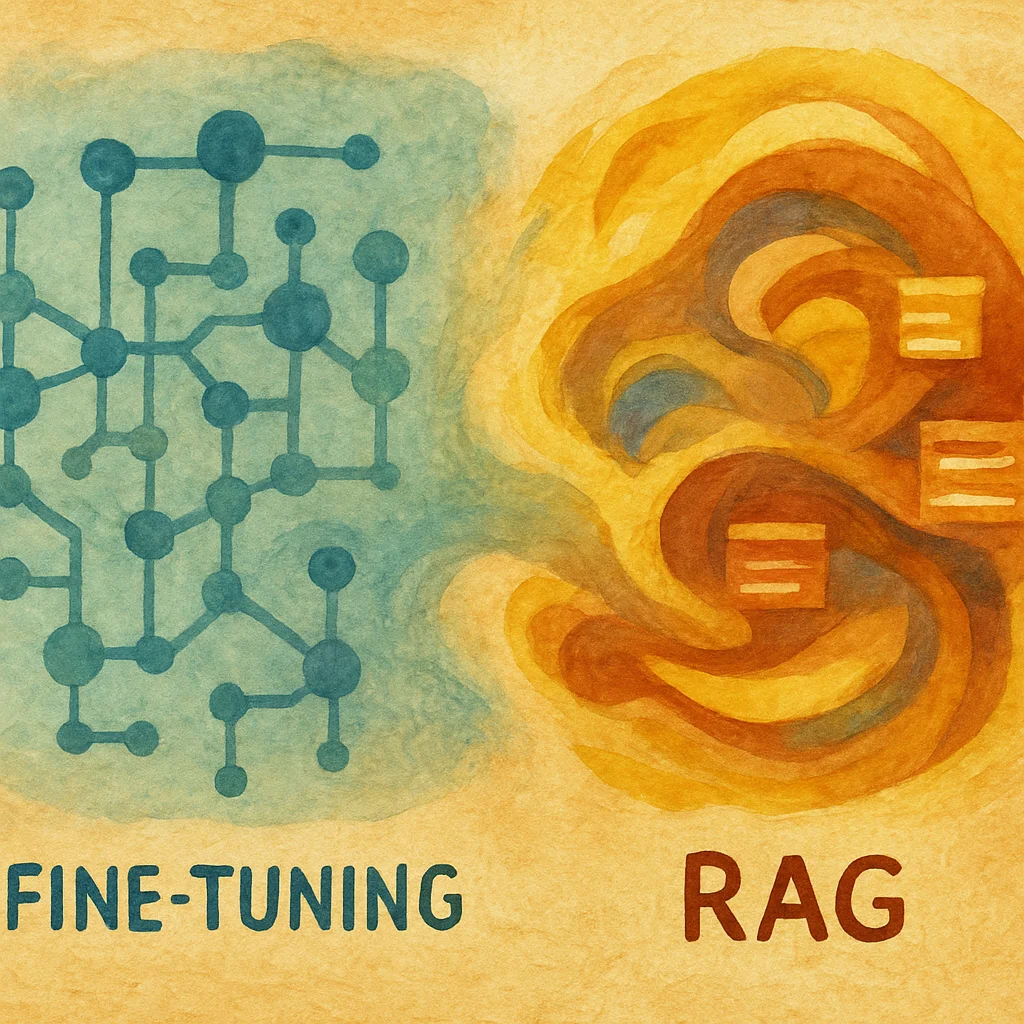
The heart of the matter lies in how each approach handles knowledge and adapts to new data. Fine-tuning adjusts the model's internal weights, embedding knowledge permanently, whereas RAG leaves the base model fixed and leverages external search over indexed documents.
Several key factors differentiate these approaches:
- Flexibility and Update Speed: RAG allows near-instant updates to knowledge simply by refreshing the underlying document store. Fine-tuning requires retraining, which can take hours or days depending on model size and hardware.
- Computational Resources: Fine-tuning large models demands significant GPU hours and energy, often limiting access to well-funded entities. RAG’s retrieval component, though it adds complexity, is generally lighter to maintain.
- Performance and Accuracy: Fine-tuned models often excel in tasks where nuanced domain understanding is critical. RAG can outperform when dealing with broad or constantly changing knowledge, though it may struggle if retrieval fails or documents contain noise.
- Scalability: RAG architectures can scale horizontally by augmenting the document index, while fine-tuning scales vertically, requiring larger models or ensembles.
- Interpretability and Control: RAG’s output can be traced back to retrieved documents, aiding transparency—valuable for compliance or audit. Fine-tuning’s learned weights are less interpretable.
"RAG represents a paradigm shift where AI models become dynamic collaborators with external knowledge, rather than static repositories." — AI researcher Dr. Leena Kapoor
In concrete terms, a legal firm deploying AI for contract analysis might prefer fine-tuning to embed complex legal concepts into the model’s core. Conversely, a financial news aggregator might adopt RAG to pull the latest market data and generate timely insights without retraining.
For a deeper dive, Froodl’s article on RAG vs Fine-Tuning: Comparing Approaches in AI Model Customization extends this technical exploration with side-by-side benchmarks and architecture diagrams.
Current Trends in 2026: Innovations Shaping RAG and Fine-Tuning
The year 2026 marks a fertile period of innovation around these two approaches. Recent breakthroughs have blurred lines, with hybrid models combining limited fine-tuning and retrieval to optimize for specific constraints.
Some notable developments include:
- Agentic RAG: An evolution of traditional RAG, agentic approaches introduce autonomous agents that iteratively query, reason, and refine retrievals, improving answer quality in complex tasks. Froodl’s analysis in Agentic RAG vs Traditional RAG: What’s the Difference? highlights how this architecture enhances contextual understanding.
- Parameter-Efficient Fine-Tuning (PEFT): Techniques such as LoRA and adapters have reduced fine-tuning costs by orders of magnitude, enabling smaller teams to customize gargantuan models without starting from scratch.
- Multimodal RAG: Integrating images, audio, and video into retrieval pipelines has expanded use cases in media, education, and surveillance, pushing RAG beyond text-centric applications.
- Privacy-Preserving Fine-Tuning: Advances in federated learning and differential privacy have empowered organizations to fine-tune models on sensitive data while maintaining compliance with global regulations.
These trends reflect a maturation of AI customization technologies, with ecosystems coalescing around open-source toolkits and cloud-native services that democratize access.
"The convergence of retrieval and fine-tuning techniques signals a new era where AI models are both knowledgeable and adaptable, tailored yet scalable." — Industry analyst Priya Menon
For readers seeking to keep pace with these rapid developments, Froodl’s Comprehensive Guide to AI Model Customization offers an updated resource tracking the latest tools, frameworks, and best practices.
Real-World Impact: Case Studies of RAG and Fine-Tuning in Action
Beyond theory and benchmarks, the proof is in deployment. Several organizations have navigated the RAG versus fine-tuning choice with distinct outcomes.
Consider a multinational pharmaceutical company aiming to accelerate drug discovery. They leveraged fine-tuning on proprietary clinical trial data, enabling the AI to predict molecular interactions with high precision. The long training times were offset by the need for deeply ingrained domain knowledge and stringent data privacy.
Contrast this with a global news platform that implemented RAG to power its AI-driven summarization and fact-checking system. The ability to index millions of news articles daily and retrieve relevant context improved both accuracy and user trust, without retraining the base model.
These examples illustrate how context governs choice. Factors influencing the decision include:
- Data volatility — how often knowledge changes
- Resource availability — computational and human expertise
- Latency requirements — response time tolerances
- Regulatory landscape — data compliance and auditability
As AI adoption grows, these considerations become strategic imperatives rather than technical footnotes.
Looking Ahead: What the Future Holds for RAG and Fine-Tuning
The future of AI customization will likely be neither RAG nor fine-tuning exclusively, but an ecosystem where their strengths interlace. Emerging paradigms suggest models that dynamically switch between retrieving fresh information and relying on embedded knowledge, optimizing for task, context, and user preference.
Key areas to watch include:
- Automated Model Adaptation: Systems that autonomously select the optimal blend of fine-tuning and retrieval based on performance metrics and operational context.
- Explainability and Trust: Enhanced transparency tools that trace AI outputs to both learned knowledge and retrieved documents, crucial for regulated industries.
- Cost-Efficient Scaling: Innovations in hardware and software that reduce the carbon footprint and financial cost of fine-tuning massive models and maintaining retrieval indices.
- Cross-Domain Transfer: Models capable of leveraging fine-tuned expertise while querying diverse external corpora, blurring domain boundaries.
For decision-makers, this evolving landscape demands a nuanced understanding of the trade-offs and an openness to hybrid strategies. Froodl’s article, RAG vs Fine-Tuning: Which Approach Should You Choose?, offers a practical framework to navigate these choices in real-world scenarios.
Ultimately, the dialogue between RAG and fine-tuning is a reflection of AI’s broader journey—from static intelligence to dynamic, context-aware collaborators. As models learn not just to remember but to seek and reason, the boundaries of possibility stretch ever wider.
0 comments
Log in to leave a comment.
Be the first to comment.