
Web Scraping for Market Research: Building Datasets From Thousands of Websites
Market research has traditionally relied on surveys, interviews, focus groups, industry reports, and manually collected competitor information. While these methods remain useful, they can become difficult to scale when businesses need to understand rapidly changing markets.
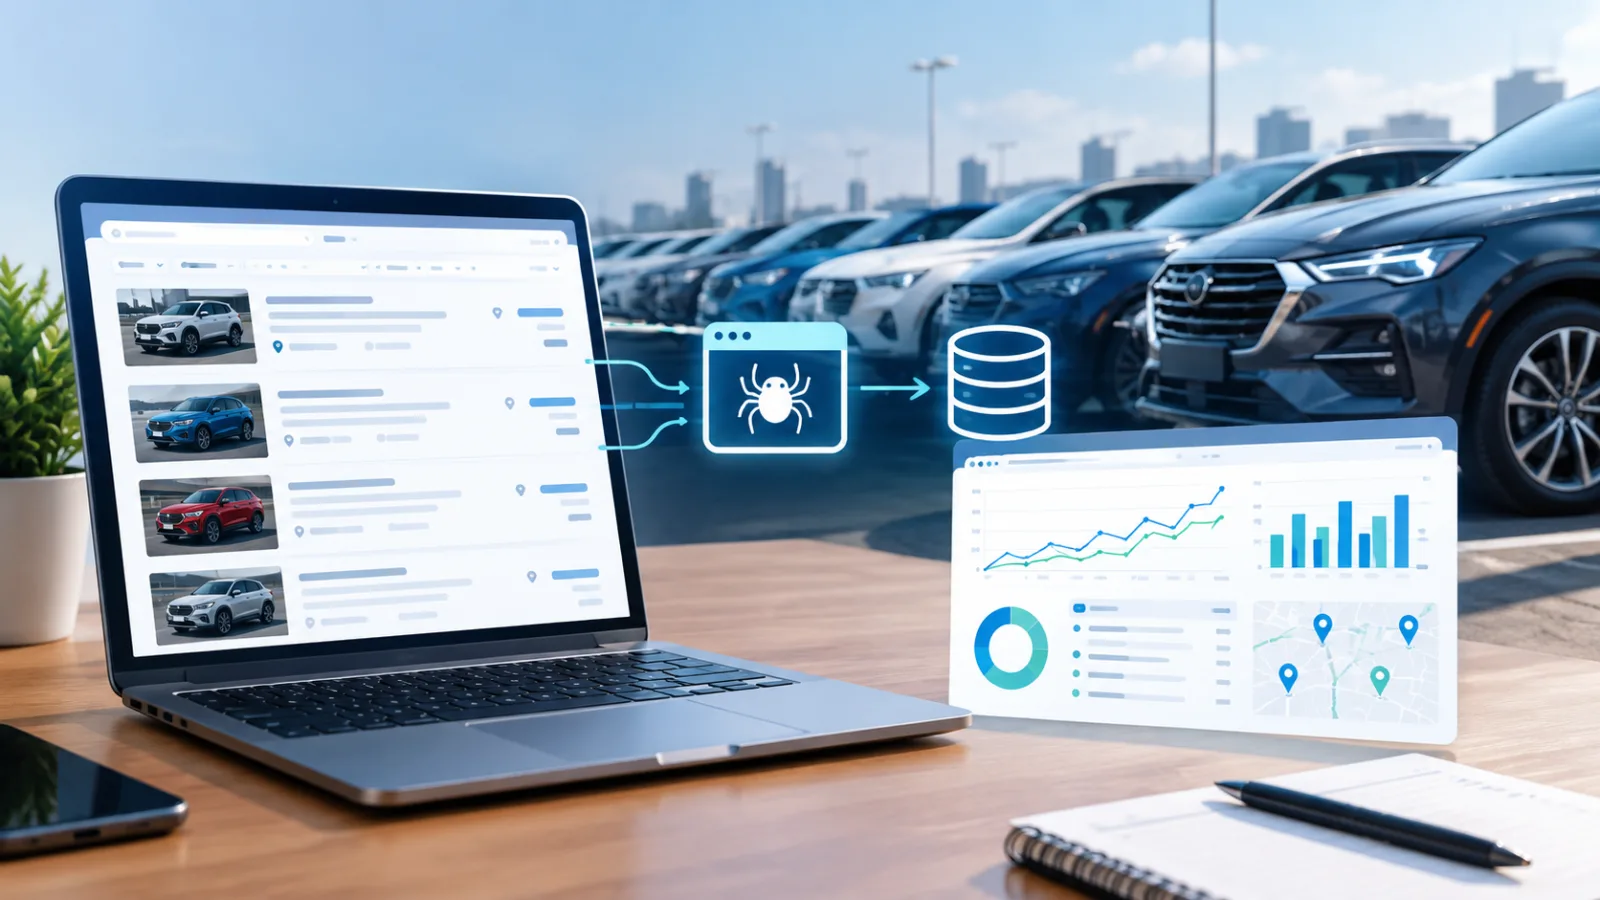
Market research web scraping provides another approach by allowing companies to collect large volumes of publicly available information from thousands of websites and transform it into structured datasets. Instead of analyzing isolated web pages, businesses can continuously collect information about products, prices, competitors, customer reviews, trends, and market activity.
What Is Market Research Web Scraping?
Market research web scraping is the automated collection of publicly available information from websites for research and analysis.
Depending on the research objective, businesses can collect:
Product names and categories
Prices and discounts
Product specifications
Customer ratings and reviews
Competitor offerings
Store and location information
Search results and rankings
Industry news and announcements
Product availability
Promotional campaigns
The collected information can then be organized into databases, spreadsheets, dashboards, or analytics systems.
This allows researchers to move beyond manually checking individual websites and instead analyze large datasets covering hundreds or thousands of sources.
Why Large Datasets Matter for Market Research
A single website can provide useful information, but it rarely represents an entire market.
Consider a company researching the consumer electronics industry. Looking at 20 competitor products may provide some understanding of pricing and features. However, analyzing thousands of products across multiple retailers and marketplaces can reveal broader pricing distributions, popular specifications, emerging brands, and product gaps.
Large datasets make it easier to identify patterns that are difficult to see through traditional research.
For example, researchers might discover that:
A specific product feature is becoming more common.
Several competitors are reducing prices within the same category.
New brands are entering a particular market segment.
Customer complaints are increasing around a specific product attribute.
Demand appears to be shifting toward a particular product type.
These insights can support product development, pricing, positioning, and expansion decisions.
Building Datasets From Thousands of Websites
Creating a useful market research dataset requires more than simply collecting web pages. Businesses first need to identify the sources and data points that matter to their research question.
A typical workflow starts with defining the target market and selecting relevant websites. These may include competitor websites, retailers, marketplaces, review platforms, directories, news publications, and industry-specific sources.
The scraper then extracts selected fields from these websites and converts them into a consistent structure.
For example:
Product → Brand → Category → Price → Rating → Reviews → Availability → URL → Date
Standardizing the information is particularly important when data comes from thousands of websites because different sources often use different names, formats, and structures for similar information.
Using Marketplace Data Scraping for Product Research
Marketplaces contain large amounts of information about products, sellers, pricing, ratings, and consumer activity.
Marketplace data scrapingcan help researchers build datasets covering thousands or millions of product listings across relevant marketplaces.
Researchers can use this data to analyze:
Price ranges across product categories
Brand presence and market positioning
Product assortment
Discount frequency
Seller activity
Ratings and review volumes
Product availability
New product introductions
For example, a brand considering entry into a new category could analyze thousands of marketplace listings to understand the competitive landscape before launching its own product.
Tracking Market Changes Over Time
One of the biggest advantages of web scraping for market research is that data can be collected repeatedly.
A one-time dataset provides a snapshot. Historical datasets provide a view of how the market is changing.
By collecting data daily, weekly, or monthly, businesses can track changes in:
Price → Product assortment → Availability → Reviews → Ratings → Promotions
This makes it possible to identify trends earlier.
For example, if average prices in a category have been declining steadily for six months, the change may indicate increasing competition or commoditization. Similarly, a sudden increase in new products could indicate that companies are entering an emerging market segment.
Combining Web Data With Internal Business Data
Web scraping becomes even more valuable when external market data is combined with internal business information.
A company could compare scraped competitor pricing with its own pricing, or combine customer demand data with marketplace product availability.
This creates a broader analytical framework.
For example:
External market data + competitor data + internal sales data = stronger market intelligence
Researchers can use these datasets to identify opportunities, benchmark performance, evaluate competitors, and support strategic planning.
Scaling Market Research Across Industries
Market research web scraping can be applied across many industries because the underlying approach is flexible.
Retailers can monitor products and pricing. Travel companies can analyze hotel rates and availability. Financial researchers can collect alternative datasets. Real estate companies can monitor property listings. B2B companies can track competitors, services, and market positioning.
The scale can also be adjusted according to the research requirement, from monitoring a few competitors to collecting information from thousands of websites.
Making Web Data Useful for Decision-Making
Large datasets alone do not create useful market intelligence. The collected information needs to be cleaned, structured, validated, and analyzed.
Businesses should establish consistent data fields, remove duplicates, monitor changes in website structures, and maintain historical records. Automated alerts and dashboards can then help researchers focus on meaningful changes instead of manually reviewing every record.
It is also important to collect only publicly available information and consider website terms, applicable privacy requirements, and relevant data protection regulations.
Turning the Web Into a Market Research Dataset
The internet contains an enormous amount of publicly available market information, but much of it is scattered across thousands of websites.
Market research web scraping provides a scalable way to bring this information together into structured datasets that can be analyzed systematically. From competitor pricing and product launches to customer sentiment and marketplace activity, regularly collected web data can provide a more current view of market conditions.
When combined with historical tracking and internal business data, web scraping can transform fragmented online information into a continuous source of market intelligence—helping businesses identify opportunities, understand competitors, and make decisions based on what is happening in the market now.
0 comments
Log in to leave a comment.
Be the first to comment.