
Snowflake Data Warehouse Optimization: Query Profiling, Clustering, and Compute Tuning
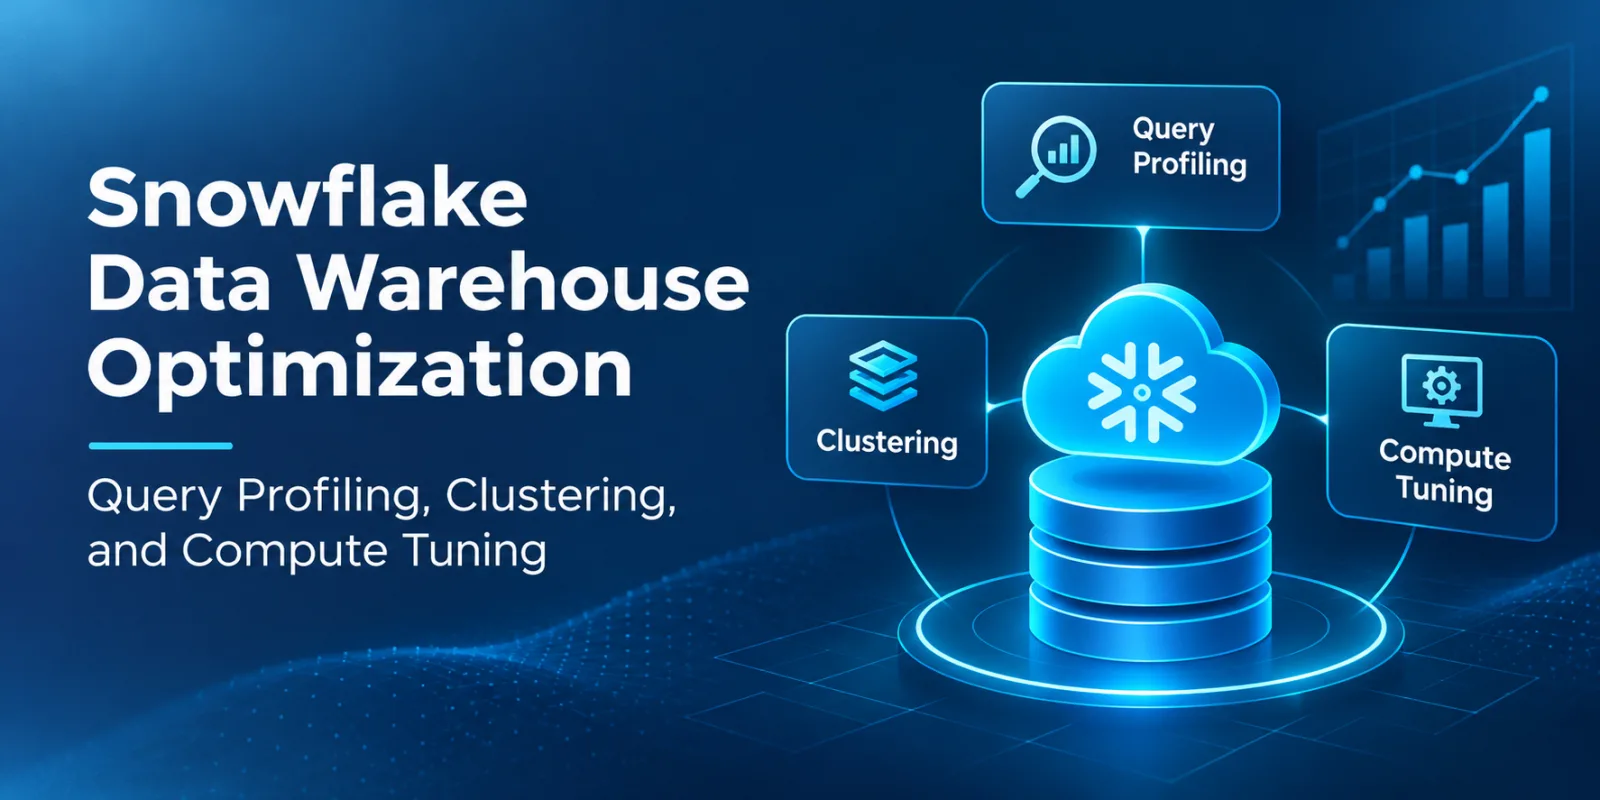
Snowflake Data Warehouse Performance Depends on Efficient Query Execution, Micro-Partition Pruning, and Appropriate Compute Allocation. Poorly Optimized SQL, Excessive Data Scanning, and Incorrectly Sized Virtual Warehouses Can Increase Query Latency and Credit Consumption.Snowflake Performance OptimizationRequires Systematic Analysis of Execution Plans, Storage Organization, and Warehouse Utilization.
Query Profiling and Execution Analysis
Snowflake's Query Profile provides operator-level execution metrics for identifying performance bottlenecks, including table scans, joins, aggregations, and data spilling.
Key diagnostic metrics include:
The SNOWFLAKE.ACCOUNT_USAGE.QUERY_HISTORY view supports historical workload analysis, including execution time, bytes scanned, and warehouse utilization indicators.
Micro-Partition Pruning and Clustering
Snowflake automatically organizes table data into compressed, columnar micro-partitions. Query performance depends partly on how effectively predicates eliminate irrelevant partitions.
Clustering keys can improve pruning for large tables with frequently filtered columns, particularly when natural data ordering is insufficient.
ALTER TABLE sales_transactions
CLUSTER BY (transaction_date, region_id);
Clustering should be evaluated using query patterns, clustering depth, and maintenance costs. Automatic Clustering consumes additional credits, making it unsuitable for every table.
Search optimisation service may provide an alternative for selective point lookups and supported search predicates.
Virtual Warehouse Sizing and Compute Tuning
Snowflake virtual warehouses provide independently scalable compute resources for SQL workloads.
Warehouse optimization involves balancing query complexity, execution time, concurrency, and credit consumption.
Scale up: Increase warehouse size for memory-intensive queries or workloads that benefit from additional compute.
Scale out: Use multi-cluster warehouses to manage concurrent query demand.
Auto-suspend: Reduce idle compute consumption through automatic warehouse suspension.
Workload isolation: Assign separate warehouses to ingestion, transformation, and reporting workloads.
Increasing warehouse size does not guarantee proportional performance improvements. Benchmarking should compare execution time and total credits consumed across configurations.
Monitoring Optimization Effectiveness
Performance tuning should be validated using representative workloads and consistent testing conditions.
Key indicators include query latency, partitions scanned, bytes spilled, warehouse queueing time, and credits consumed per workload.
The WAREHOUSE_METERING_HISTORY and QUERY_HISTORY views support compute-cost analysis and workload-level performance monitoring.
Snowflake Performance Optimization With Netlink
As a Snowflake Services Select Tier Partner, Netlink supports query profiling, SQL optimization, clustering strategy assessment, warehouse configuration, and workload performance tuning.
By combining execution diagnostics with compute-cost analysis, Netlink helps enterprises establish measurable performance improvements while maintaining efficient Snowflake resource utilization.
0 comments
Log in to leave a comment.
Be the first to comment.