
Overcoming Data Quality Challenges in Large-Scale Text Annotation Projects
Discover how to overcome data quality challenges in large-scale text annotation projects with proven strategies, quality assurance, and expert annotation services.
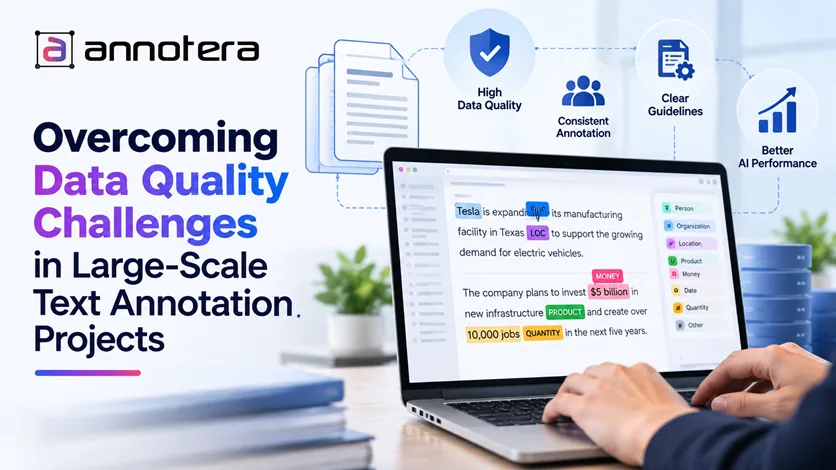
As Artificial Intelligence (AI) and Natural Language Processing (NLP) Technologies Continue to Evolve, Businesses Increasingly Depend on Accurately Labeled Text Data to Train Reliable Machine Learning Models. From Conversational AI and Sentiment Analysis to Named Entity Recognition (NER) and Large Language Models (LLMs), High-Quality Annotated Datasets Are Essential for Developing Intelligent Applications. However, Maintaining Consistent Data Quality Becomes Significantly More Challenging When Annotation Projects Involve Millions of Text Records, Multiple Languages, and Complex Labeling Requirements.
Large-scale text annotation projects often encounter issues such as inconsistent labeling, ambiguous language, human error, and inadequate quality control. If these problems remain unresolved, they can compromise model performance, increase operational costs, and delay AI development.
Understanding these challenges and implementing effective quality management practices can help organizations build dependable datasets that support long-term AI success.
Why Data Quality Matters in Large-Scale Text Annotation
Text annotation involves assigning meaningful labels to textual data so that AI models can recognize patterns, interpret language, and generate relevant responses. Common annotation tasks include intent classification, sentiment analysis, entity extraction, text categorization, and linguistic labeling.
The quality of annotated data directly influences how well an AI model learns from its training examples. Incorrect labels can introduce bias, reduce prediction accuracy, and cause models to misinterpret user intent. These risks become more significant when errors are repeated across large datasets.
For example, a customer support chatbot trained on incorrectly labeled queries may confuse refund requests with product inquiries. Similarly, an NER model may incorrectly identify an organization as a person's name if annotation guidelines are unclear.
Therefore, data quality must remain a priority throughout the annotation lifecycle rather than being treated as a final inspection step.
Common Data Quality Challenges in Large-Scale Text Annotation Projects
1. Inconsistent Labeling Across Annotators
When hundreds of annotators work on the same dataset, differences in interpretation can produce inconsistent labels. One annotator may classify a customer message as negative sentiment, while another may consider it neutral.
These discrepancies frequently arise when categories overlap or annotation instructions lack precise definitions.
How to overcome it: Establish standardized annotation guidelines with clear definitions, decision rules, and examples of difficult cases. Conduct calibration exercises before production begins and periodically review disagreements to maintain consistent interpretation across teams.
2. Ambiguous Language and Contextual Complexity
Human language is rarely straightforward. Words and phrases can have different meanings depending on context, tone, cultural references, and surrounding sentences. Sarcasm, idioms, abbreviations, and domain-specific terminology make annotation even more complicated.
For instance, the statement "That was just great" could express genuine satisfaction or sarcasm, depending on the conversation.
How to overcome it: Provide annotators with sufficient contextual information and establish rules for handling ambiguous examples. Introduce escalation procedures for uncertain cases and maintain an adjudication process in which experienced reviewers resolve disagreements.
3. Human Error and Annotation Fatigue
Large-scale projects often require repetitive labeling across thousands or millions of text samples. Over time, annotators may experience fatigue, reducing concentration and increasing the likelihood of missed entities, incorrect categories, or incomplete annotations.
Strict productivity targets can further compromise accuracy when teams prioritize output volume over quality.
How to overcome it: Divide workloads into manageable batches, provide regular breaks, and monitor quality alongside productivity. Use automated checks to identify missing fields, invalid labels, and formatting inconsistencies before datasets move to the next production stage.
4. Poorly Defined Annotation Guidelines
Incomplete instructions can create confusion about label boundaries, exceptions, and edge cases. Even experienced annotators may produce unreliable results when project requirements are unclear or frequently revised.
This challenge becomes particularly serious in specialized applications such as healthcare documentation, financial text analysis, and legal information extraction.
How to overcome it: Develop a comprehensive annotation handbook before scaling production. Include positive and negative examples, edge-case scenarios, labeling hierarchies, and decision-making rules. Version-control the guidelines and communicate approved changes to all relevant team members.
5. Managing Multilingual and Domain-Specific Data
Global AI applications often require annotated datasets across different languages, dialects, and cultural contexts. Directly translating annotation guidelines may not account for linguistic differences, regional expressions, or variations in sentiment.
Similarly, industry-specific terminology can create challenges when annotators lack the necessary subject knowledge.
How to overcome it: Use linguistically proficient annotators and domain-trained reviewers. Adapt labeling instructions to each language and application rather than relying exclusively on direct translations. Conduct language-specific quality audits to identify recurring errors and cultural interpretation issues.
Best Practices for Improving Text Annotation Quality at Scale
Addressing data quality challenges requires a structured approach that combines human expertise, standardized processes, and technology-enabled validation.
1. Implement Multi-Level Quality Assurance
A reliable quality assurance framework should include checks at multiple stages of the annotation process. Initial validation can identify formatting errors and missing labels, while secondary reviews can evaluate semantic accuracy and adherence to guidelines.
Random sampling, risk-based sampling, and targeted reviews of difficult examples can help identify problems before they affect entire datasets. High-impact errors should trigger root-cause analysis and corrective action.
2. Use Inter-Annotator Agreement Metrics
Inter-annotator agreement measures the consistency of labels assigned by different annotators to the same data. Depending on the task and label structure, teams may use Cohen's kappa, Fleiss' kappa, or Krippendorff's alpha.
These metrics help identify unclear instructions, difficult categories, and annotators who may require additional training. However, agreement scores should be interpreted alongside expert review because annotators can consistently apply an incorrect labeling rule.
3. Combine Human Expertise With Automated Validation
Automation can improve efficiency by detecting duplicate records, validating required fields, identifying malformed outputs, and flagging potentially inconsistent labels. Machine learning models can also assist with pre-labeling or highlighting uncertain examples for human review.
Nevertheless, automated systems should support rather than replace human judgment, especially when interpreting context, sarcasm, nuanced intent, or specialized terminology.
4. Monitor Quality With Measurable KPIs
Organizations should define quality metrics before launching a large annotation initiative. Useful indicators include label accuracy, inter-annotator agreement, reviewer rejection rate, defect rate, and rework percentage.
Regular dashboards and quality reports help project managers identify performance trends, investigate recurring errors, and allocate review resources effectively.
5. Maintain Continuous Feedback and Improvement
Data quality management should evolve throughout the project. Feedback from reviewers, model evaluation results, and newly discovered edge cases can reveal weaknesses in existing annotation guidelines.
Teams should document these findings, update instructions through controlled revisions, and retrain annotators when necessary. This approach helps maintain consistency as datasets grow and AI requirements change.
How Text Annotation Outsourcing Services Support Quality at Scale
Managing a large annotation workforce internally requires substantial investment in recruitment, training, project management, quality assurance, and technical infrastructure. Businesses must also maintain consistent output as project volumes and labeling requirements evolve.
Working with a specialized text annotation company can help organizations establish structured workflows, access trained annotation teams, and implement quality controls suited to specific AI applications.
Professional text annotation outsourcing services can support tasks such as intent classification, sentiment analysis, named entity recognition, text categorization, and LLM training data preparation. Depending on project requirements, these services may include customized annotation guidelines, multi-stage reviews, adjudication workflows, and performance reporting.
However, outsourcing alone does not guarantee high-quality data. Organizations should evaluate providers based on their quality assurance methodology, data security practices, scalability, domain expertise, and ability to meet defined acceptance criteria.
A collaborative approach involving clear requirements, regular communication, and measurable quality benchmarks helps ensure that outsourced annotation aligns with business objectives.
Build Reliable AI Datasets With Annotera
Large-scale text annotation requires more than labeling high volumes of information. It demands consistent guidelines, trained annotators, transparent quality metrics, and continuous improvement.
Annotera helps businesses address text annotation challenges through structured data labeling workflows designed to support AI and NLP development. By combining human expertise with quality-focused processes, organizations can prepare more reliable datasets for applications ranging from conversational AI and information extraction to advanced language model training.
Whether your organization is developing an NLP solution or preparing training data for generative AI, prioritizing annotation quality can reduce rework, strengthen model reliability, and improve the value of your data investments.
Looking to improve the quality of your AI training datasets? Partner with Annotera to explore text annotation solutions aligned with your project requirements and quality standards.
0 comments
Log in to leave a comment.
Be the first to comment.