
MuleSoft Integration Monitoring: Tracking API Performance and Failures
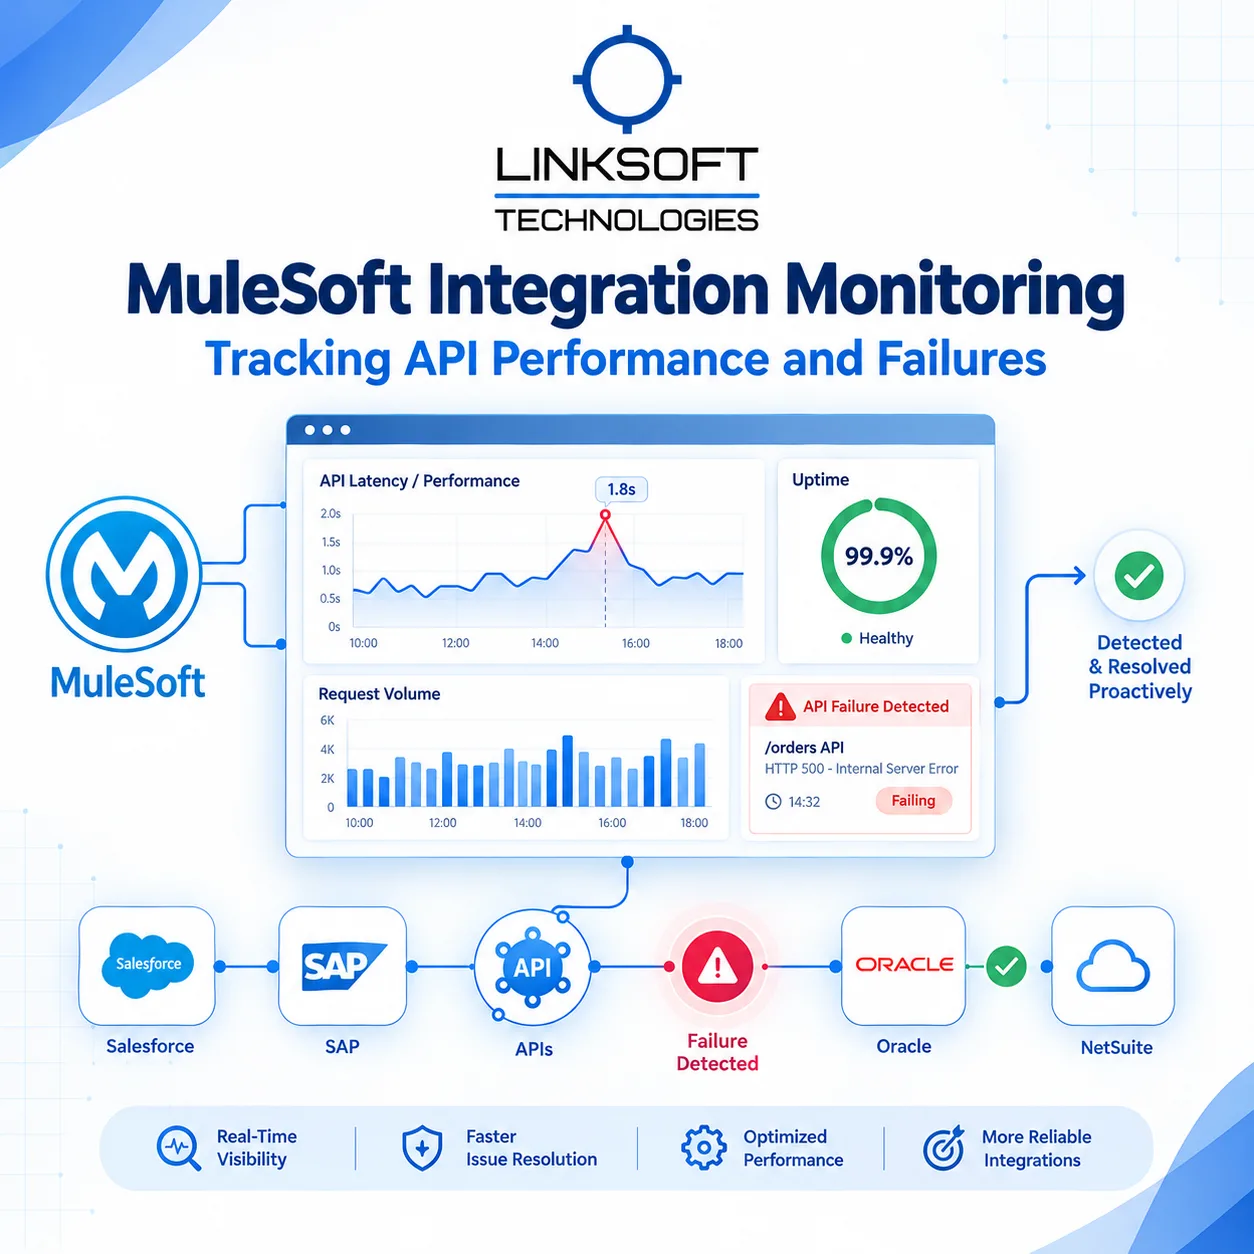
MuleSoft integrations sit between your most critical systems, so when an API slows down or a flow fails, the impact spreads fast: orders stall, customer records drift out of sync, and partner calls time out. Effective MuleSoft integration monitoring means tracking API performance continuously, catching failures before users report them, and having enough context to fix the root cause quickly.
This guide covers the metrics that matter, the monitoring tools built into the Anypoint Platform, how to track and diagnose failures, and the practices that keep integrations healthy in production.
Key Metrics for Tracking MuleSoft API Performance
Five metric groups tell you most of what you need to know about an API's health. Track them per API and per environment, so a spike in production is never hidden by quiet test traffic.
Percentiles matter more than averages. A healthy average can hide a long tail of slow calls that time out for a real share of users. Separating 4xx from 5xx errors also saves time: 4xx usually means a consumer problem, while 5xx points to your flows, connectors, or backend systems.
Native Monitoring Tools in Anypoint Platform
Anypoint Monitoring is the center of MuleSoft observability, and most teams can cover their core needs without a third-party tool. Its main components are:
Built-in dashboards show app and API metrics out of the box: response times, request volume, failures, and JVM resource usage, broken down by worker for multi-worker apps.
Custom dashboards let you combine metrics that matter to a specific business flow, such as order-sync latency next to Salesforce connector errors. These are part of the Advanced and Titanium tiers.
Anypoint Insights groups apps and APIs into logical entities that mirror your architecture, so you can see the health of a whole capability instead of one app at a time.
Log search aggregates logs across deployments. MuleSoft rolled out an enhanced Log Search experience during 2026.
Distributed tracing follows a transaction across multiple Mule apps, which is essential for API-led designs with experience, process, and system layers.
API Functional Monitoring runs scheduled synthetic tests against endpoints, catching broken contracts even when real traffic is low.
Telemetry Exporter streams real-time data in OpenTelemetry format to tools like Splunk, Datadog, or New Relic, so MuleSoft fits into a wider observability stack.
Alerting is split across three places. Anypoint Monitoring handles basic and custom dashboard alerts, with thresholds checked every five minutes. API Manager raises operational API alerts, such as policy violations and response-time breaches. Runtime Manager covers server and app events, like a deployment failure or a worker crash. Note that alerts created in API Manager and Runtime Manager do not appear on the Anypoint Monitoring alerts page, so document where each one lives.
Feature availability depends on your subscription: Starter plans include built-in dashboards, functional monitoring, and single-app log search, while custom metrics, custom alerts, and telemetry export need the Advanced package.
Tracking and Diagnosing Integration Failures
Failures are easiest to fix when each one leaves a clear, searchable trail. Most production incidents in MuleSoft fall into a few patterns: backend timeouts, connectivity errors such as HTTP:CONNECTIVITY, data transformation errors in DataWeave, expired credentials, and resource exhaustion on undersized workers.
A practical diagnosis workflow looks like this:
Confirm the alert. Check the built-in dashboard for the affected API to see when errors started and whether latency rose first.
Narrow the scope. Use Anypoint Insights or the Application Network view to see whether the failure is in one app or spreading across dependent layers.
Follow the transaction. Use distributed tracing or a shared correlation ID to locate the exact flow and connector that failed.
Read the logs. Search by correlation ID and error type to find the payload, the error message, and the upstream response.
Check recent changes. Compare against recent deployments, policy updates, or certificate rotations in Runtime Manager and API Manager.
This workflow depends on good error handling in the Mule apps themselves. Use On Error Propagate and On Error Continue scopes deliberately, map errors to meaningful types, and log a structured message with the correlation ID, error type, and affected system. Generic catch-all handlers that swallow errors make failures invisible to every monitoring tool.
Best Practices for MuleSoft Integration Monitoring
Alert on symptoms users feel. Prioritize error rate and p95 latency over raw CPU, and tie thresholds to your SLAs.
Use severity levels. Reserve critical alerts for issues that need immediate action, so on-call teams do not learn to ignore notifications.
Propagate correlation IDs. Pass one ID through every layer of an API-led architecture so logs and traces line up.
Add synthetic tests for key APIs. Functional monitoring catches failures during low-traffic hours, before the morning rush finds them.
Build business-level dashboards. Pair technical metrics with outcomes such as orders processed or records synced.
Export telemetry when you need a single view. If your organization already runs a central observability platform, stream MuleSoft data into it rather than running two separate alert systems.
Review alerts regularly. Retire noisy alerts and add new ones after every incident review.
Conclusion
Strong MuleSoft integration monitoring combines the right metrics, well-placed alerts, and Mule apps built to report their own failures clearly. Start with built-in dashboards and API Manager alerts, add tracing and correlation IDs as your API network grows, and export telemetry when you need one view across the enterprise. The result is fewer surprises, faster fixes, and integrations your business can rely on.
0 comments
Log in to leave a comment.
Be the first to comment.