
How to Build a Production-Ready RAG AI Chatbot From Scratch
Key Takeaways
- RAG enables AI chatbots to answer questions using private, proprietary, and frequently changing business data rather than relying solely on an LLM's training data.
- A production RAG chatbot requires more than connecting an LLM to a vector database; data preparation, retrieval quality, evaluation, security, and monitoring are equally important.
- Modern RAG architectures can combine vector, keyword, semantic, and hybrid search to improve retrieval relevance.
- Agentic RAG is becoming useful for complex queries where the system needs to decide which sources to search and how many retrieval steps to perform.
- AI adoption is accelerating rapidly. Stanford's 2026 AI Index reports that 88% of surveyed organizations used AI in 2025, while generative AI was used in at least one business function by 70%.
- Successful RAG implementation should be treated as an ongoing engineering and evaluation process rather than a one-time chatbot deployment.
Why Businesses Are Moving Beyond Conventional AI Chatbots
Traditional AI chatbots can produce fluent and convincing answers, but fluency does not necessarily mean factual accuracy.
An LLM may know a great deal about general topics while knowing nothing about a company's latest product documentation, internal policies, customer records, technical manuals, contracts, or proprietary research.
This creates a fundamental problem for enterprise AI: How can an AI model answer questions using information it was never trained on?
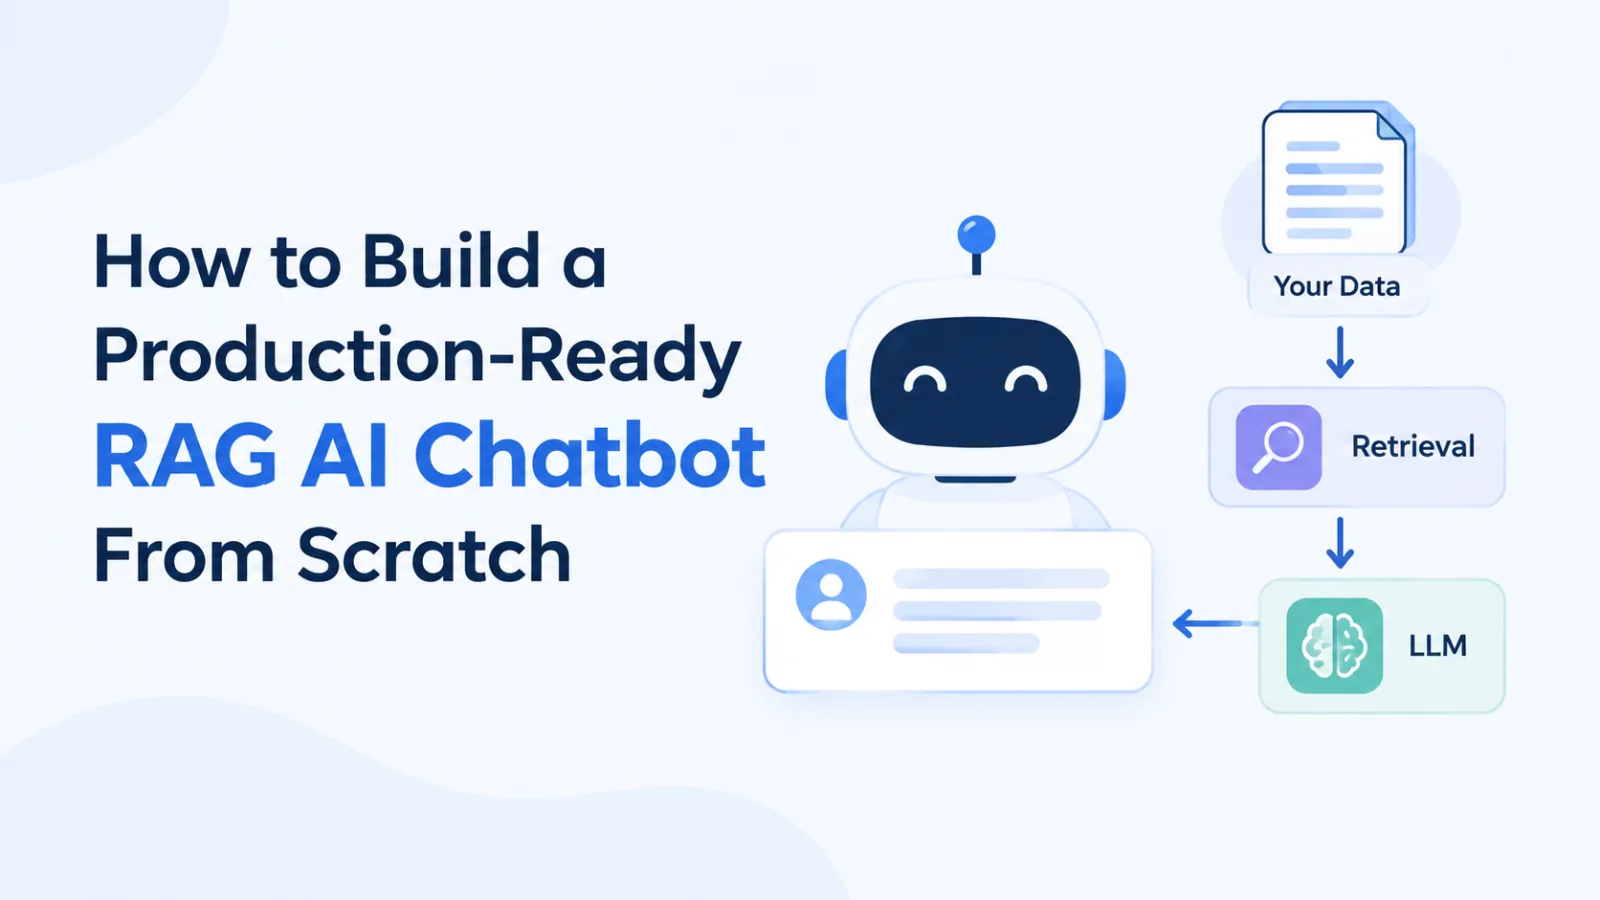
Retrieval-Augmented Generation, or RAG, addresses this problem by connecting the language model with an organization's own knowledge sources.
Microsoft describes RAG as a pattern that combines search with large language models so responses can be grounded in specific organizational data. The system retrieves relevant information, supplies it to the model as context, and then generates an answer based on that context.
That makes RAG particularly useful when businesses want to build an AI chatbot with RAG integration rather than deploy a generic conversational bot.
What Happens Inside a RAG-Powered AI Chatbot?
At a high level, a RAG chatbot has two interconnected workflows: knowledge ingestion and question answering.
1. Data Ingestion
Business information may come from:
- PDFs and documents
- Websites
- Product catalogs
- Knowledge bases
- CRM systems
- Databases
- SharePoint or cloud storage
- Internal APIs
- Support tickets
- Technical documentation
The system first extracts and cleans this information.
2. Chunking
Large documents are divided into smaller, meaningful sections.
This is important because retrieving an entire 100-page document for every question would be inefficient. Instead, the system attempts to retrieve only the portions relevant to the user's query.
Microsoft's current RAG architecture guidance specifically identifies chunking, metadata enrichment, embeddings, and indexing as important stages in the data pipeline.
3. Embedding and Indexing
Each content chunk can be converted into a numerical representation called an embedding.
These embeddings allow the system to perform semantic similarity searches.
The resulting vectors and associated metadata are stored in a searchable index or vector database.
4. Retrieval
When a user asks:
“What is our refund policy for enterprise customers?”
the chatbot converts the query into a searchable representation and retrieves relevant content.
A sophisticated implementation may combine:
Keyword search + semantic search + vector search + metadata filtering
rather than depending on one retrieval method.
5. Augmentation
The retrieved information is placed into the context supplied to the LLM.
The model then receives something similar to:
User question + retrieved business information + system instructions
6. Generation
Finally, the LLM generates the response using the retrieved information.
A mature implementation can also provide citations or references to the underlying documents, improving transparency and allowing users to verify the answer.
The Architecture Behind a Production RAG Chatbot
A practical enterprise architecture can look like:
User → Chat Interface → API/Orchestrator → Query Processing → Retrieval Layer → Knowledge Base/Vector Index → LLM → Response + Citations
Behind this conversational layer sits a separate data pipeline:
Documents → Parsing → Chunking → Metadata → Embeddings → Indexing → Evaluation
This separation is important because updating the chatbot's knowledge does not necessarily require retraining the underlying LLM.
For example, if a company updates its employee handbook, the new document can be processed and indexed so the chatbot can use the latest information.
Microsoft's current architecture documentation similarly separates the RAG application flow from the data pipeline responsible for preparing and indexing knowledge.
How to Build an AI Chatbot With RAG Integration
A reliable development process usually involves several stages.
Step 1: Define the Use Case
Start with the business problem instead of the technology.
Is the chatbot intended for:
- Customer support?
- Employee assistance?
- Technical troubleshooting?
- Healthcare knowledge?
- Legal document search?
- Product discovery?
- Financial research?
- Internal enterprise knowledge?
The use case determines the data sources, security model, retrieval strategy, and evaluation criteria.
Step 2: Prepare the Knowledge Base
Poor source data produces poor answers.
Documents should be cleaned, categorized, deduplicated, and enriched with useful metadata such as:
- Document type
- Department
- Date
- Product
- Region
- Access level
- Version
Step 3: Select the Retrieval Strategy
Different applications may require different approaches.
A simple knowledge assistant may use vector search, while an enterprise system could benefit from hybrid search, reranking, filters, and query rewriting.
Step 4: Select the LLM
The model should be selected according to:
- Accuracy
- Context-window requirements
- Latency
- Cost
- Privacy requirements
- Deployment environment
- Tool-calling capabilities
Step 5: Implement Security
Security should be designed into the RAG architecture.
A chatbot should not retrieve information simply because that information exists in the database.
For example, an employee may be authorized to access HR policies but not confidential executive documents.
RAG systems can expose sensitive information if retrieval permissions and prompting are poorly designed, making access controls and data governance critical.
Step 6: Evaluate Before Deployment
This is where many chatbot projects fall short.
A production RAG system should be evaluated for:
- Retrieval relevance
- Answer accuracy
- Groundedness
- Citation correctness
- Hallucination rate
- Latency
- Cost per query
- Failure cases
Microsoft recommends evaluating individual stages as well as the overall user experience rather than treating RAG quality as a single metric.
Where RAG System Development Services Add Value
Building a prototype is relatively straightforward. Building a reliable enterprise RAG system is different.
RAG system development services can cover the complete lifecycle, including:
- RAG architecture design
- Enterprise data integration
- Document processing pipelines
- Vector database implementation
- Embedding and retrieval optimization
- LLM integration
- API and application development
- Authentication and authorization
- Evaluation frameworks
- Monitoring and continuous optimization
This becomes particularly valuable when an organization has multiple knowledge sources or complex permission requirements.
RAG Is Also Evolving Into Agentic AI
Standard RAG generally follows a predefined sequence:
Question → Search → Retrieve → Generate
But complex enterprise questions may require several searches.
For example:
“Which products are affected by the latest regulation, and which of our customers purchased those products?”
The system may need to search regulatory information, product data, and customer records before generating an answer.
Agentic RAG allows an AI agent to treat retrieval as a tool and decide dynamically which sources to query and whether additional retrieval steps are required.
This represents an important direction for organizations planning their next generation of AI assistants.
Also Read: Build AI Chatbot With RAG Integration
The Business Case for RAG
The broader AI market provides a strong reason to invest in practical AI infrastructure.
Stanford's 2025 AI Index reported that organizational AI adoption increased from 55% in 2023 to 78% in 2024.
Its 2026 report indicates that adoption continued rising, with 88% of surveyed organizations reporting AI use in 2025.
The implication is straightforward: businesses are moving beyond experimenting with AI and increasingly looking for systems that can work with their own operational data.
RAG fits this transition because it provides a bridge between powerful general-purpose LLMs and enterprise-specific knowledge.
Final Perspective
The real value of RAG is not simply that it makes a chatbot “smarter.”
Its value comes from connecting conversational AI with trusted, relevant, current, and permission-controlled information.
Organizations looking to build an AI chatbot with RAG integration should therefore focus less on simply choosing an LLM and more on the complete system: data quality, retrieval architecture, security, evaluation, monitoring, and user experience.
The best RAG chatbot is not necessarily the one with the biggest model. It is the one that can consistently retrieve the right information, understand its limitations, and deliver a useful answer grounded in reliable business data.
0 comments
Log in to leave a comment.
Be the first to comment.