
How Healthcare Researchers Can Collect Public Data From Hospital and Clinic Websites
Healthcare researchers increasingly rely on publicly available information to understand healthcare access, compare services, study provider networks, and identify changes in medical facilities. Hospital and clinic websites contain valuable data, including provider directories, specialties, locations, operating hours, accepted insurance plans, and available services.
However, collecting this information manually across hundreds or thousands of websites is time-consuming and difficult to maintain. Healthcare web scraping provides a way to gather publicly accessible healthcare information at scale, transforming scattered website content into structured datasets that researchers can analyze.
What Public Healthcare Data Can Researchers Collect?
Hospital and clinic websites often publish information that supports research and healthcare market analysis. Depending on the website and applicable restrictions, researchers may collect:
Facility information: Hospital and clinic names, addresses, phone numbers, and locations
Provider directories: Physician names, departments, specialties, and professional qualifications
Medical services: Diagnostic procedures, treatment options, departments, and areas of specialization
Appointment information: Booking links, consultation availability indicators, and scheduling instructions
Operating details: Visiting hours, emergency department hours, and holiday schedules
Insurance information: Accepted insurance providers and payment-related information
Healthcare resources: Patient education materials, clinical program descriptions, and public announcements
Facility changes: New departments, relocated clinics, discontinued services, or updated contact details
Researchers should distinguish between information that is publicly displayed and information that is appropriate to collect. Public availability does not automatically eliminate privacy, contractual, or legal considerations.
Why Manual Collection Becomes Difficult
A single hospital website may organize information across multiple pages, while another may use searchable directories, PDFs, or location-specific subdomains. Provider names may appear in different formats, specialties may use inconsistent terminology, and contact details may change frequently.
Manual research introduces several challenges:
Inconsistent formats: Different websites label the same information differently.
Time-consuming updates: Rechecking provider directories and service pages requires repeated effort.
Duplicate records: The same physician may appear across multiple departments or locations.
Incomplete coverage: Researchers may overlook pages, documents, or facilities.
Data-quality issues: Missing fields, outdated information, and inconsistent naming can affect analysis.
A structured collection process helps researchers address these issues before the data reaches their analytical workflows.
How Healthcare Web Scraping Works
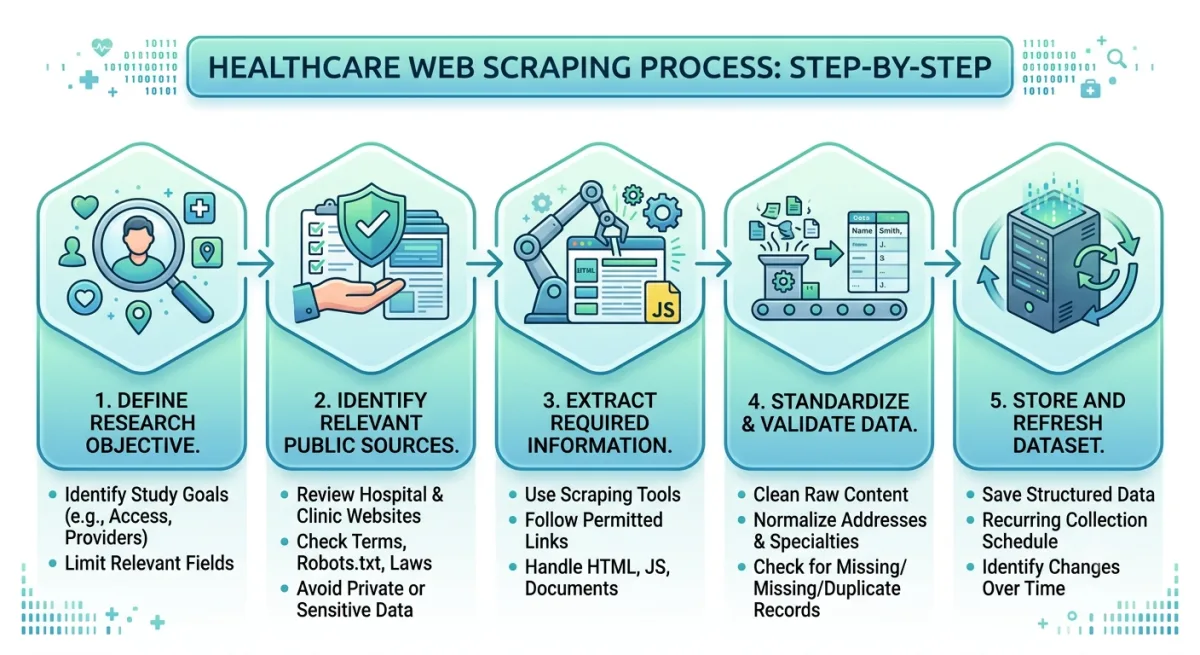
Healthcare web scraping involves using automated software to retrieve publicly accessible website content and extract selected information into a structured format.
A typical workflow includes the following steps:
1. Define the Research Objective
Researchers should first determine what they need to study. A project focused on healthcare access may require facility locations, specialties, and operating hours. A provider-network study may prioritize physician names, departments, and affiliations.
Defining the objective helps limit collection to relevant fields and reduces unnecessary requests.
2. Identify Relevant Public Sources
Potential sources include hospital websites, clinic directories, healthcare system location pages, public provider listings, and publicly accessible documents.
Researchers should review each website's terms of use, robots.txt instructions, access restrictions, and applicable laws before collecting data. Websites that require authentication or expose sensitive patient information should not be treated as ordinary public-data sources.
3. Extract the Required Information
Scraping tools can identify relevant page elements, follow permitted links, and extract fields such as facility names, addresses, specialties, and service descriptions. Some websites use structured HTML, while others require processing JavaScript-rendered content or downloadable documents.
The extraction method should match the website's structure rather than assume every source follows the same format.
4. Standardize and Validate the Data
Raw website content is rarely ready for analysis. Researchers may need to standardize specialty names, normalize addresses, separate phone numbers from descriptive text, and convert operating hours into consistent fields.
Validation checks can identify missing values, duplicate facilities, invalid URLs, and conflicting records. For example, a clinic listed under two departments may need to be linked to a single facility record.
5. Store and Refresh the Dataset
Healthcare information changes over time. Providers join or leave organizations, clinics relocate, services are added, and operating hours are updated.
A recurring collection schedule allows researchers to compare new data with previous versions and identify meaningful changes. Maintaining timestamps and source URLs also improves traceability.
Legal, Ethical, and Privacy Considerations
Healthcare research requires particular attention to privacy and responsible data handling. Researchers should focus on information intentionally published for public access and avoid collecting patient records, protected health information, login-protected content, or other sensitive data.
Before starting a project, teams should review applicable privacy laws, website terms, access restrictions, and institutional research requirements. They should also use reasonable request rates, respect technical restrictions, and avoid placing unnecessary load on healthcare websites.
Data minimization is another important principle. If a study only requires facility locations and specialties, collecting additional personal details about individual providers may not be necessary.
When to Work With Web Scraping Companies
Researchers with limited technical resources may work with Web scraping companies to collect and maintain public healthcare datasets. These providers can help with website discovery, extraction workflows, data cleaning, monitoring, and scheduled updates.
When evaluating a provider, researchers should ask:
Can the service collect only publicly accessible information?
How does it handle website restrictions and changing page structures?
Are source URLs and collection timestamps included?
Can the output be delivered in CSV, JSON, or another research-friendly format?
How are duplicates, missing values, and data changes handled?
What processes are in place to protect sensitive information?
The right approach depends on the research objective, source complexity, and required update frequency.
Turning Public Healthcare Data Into Research Insights
Once collected and standardized, public healthcare data can support a range of research activities. Researchers may map healthcare facilities by region, study the distribution of medical specialties, compare service availability, analyze provider-network changes, or identify gaps in publicly listed healthcare resources.
The value of the dataset depends not only on how much information is collected, but also on its accuracy, consistency, and freshness. A smaller, well-validated dataset may be more useful than a large collection of unverified records.
Conclusion
Hospital and clinic websites provide a valuable source of public information for healthcare research. Through a carefully designed healthcare web scraping workflow, researchers can collect facility details, provider directories, services, and other relevant information more efficiently than through manual research alone.
The most reliable projects combine responsible data collection, clear research objectives, strong validation, and regular updates. By treating public healthcare data as a structured and maintainable research asset, organizations can support more informed analysis while respecting privacy, legal, and ethical boundaries.
0 comments
Log in to leave a comment.
Be the first to comment.