
How Can a High-Traffic Application Handle Millions of Requests in a System Design Course?
System Design Course
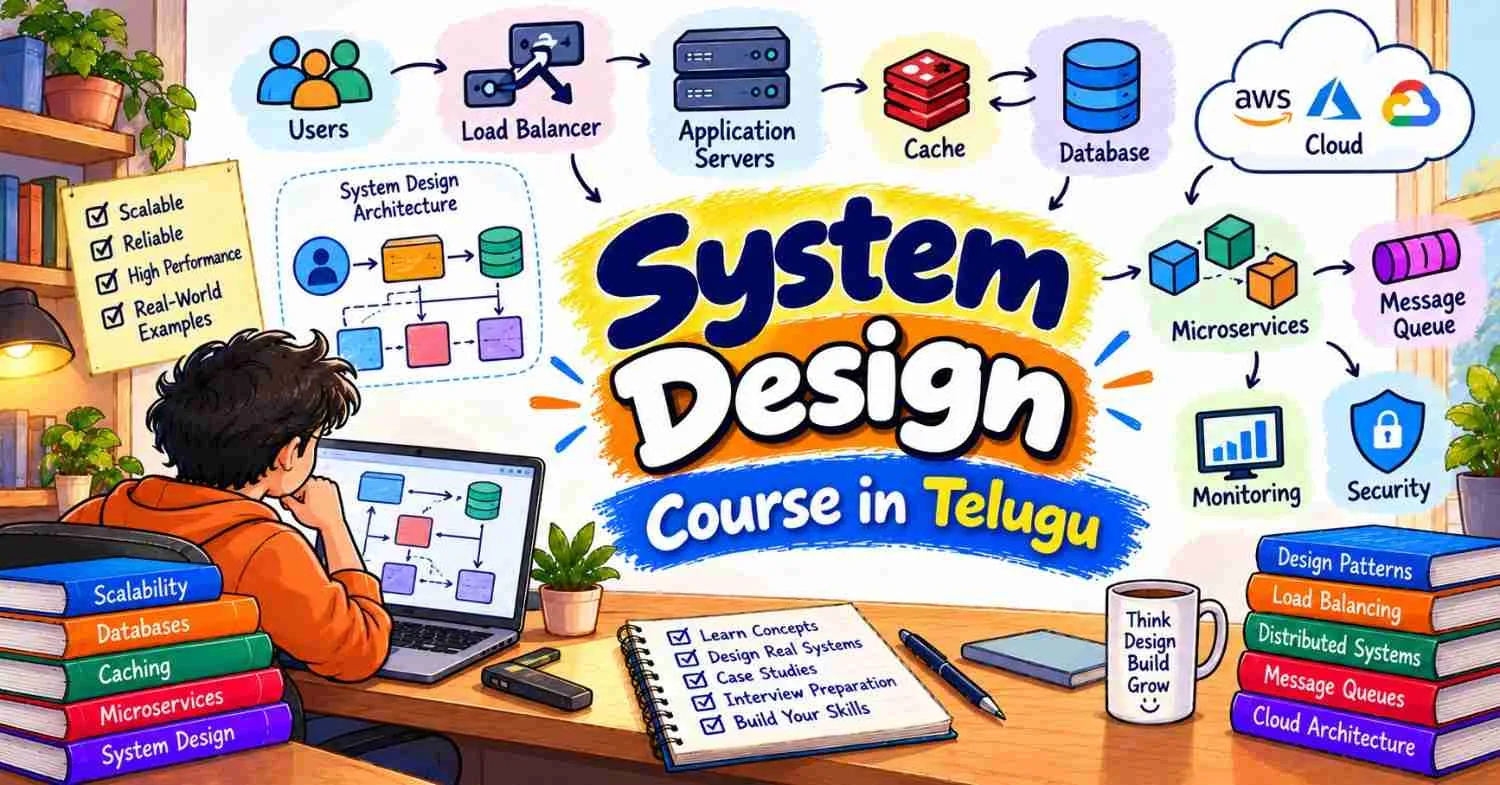
A high-traffic application handles millions of requests by distributing work across multiple layers instead of expecting one server or database to process everything. Techniques such as horizontal scaling, load balancing, caching, database optimization, asynchronous processing, and traffic control can work together to increase capacity. Understanding this process in a System Design Course helps learners see that large-scale architecture is not about one powerful technology but about removing bottlenecks throughout the request path.
Where Does High-Traffic System Design Begin?
Imagine a social media application that initially serves a few thousand users. One application server and one database may be enough for its early requirements.
As the platform grows, millions of users may open feeds, view profiles, upload content, post comments, and interact with other users. Traffic may also change dramatically throughout the day.
Before redesigning the architecture, engineers need to understand the workload.
A statement such as “the application has millions of users” is not enough. A million registered accounts and a million simultaneous requests represent very different infrastructure requirements.
Designers therefore examine expected requests per second, read-to-write ratio, data volume, peak traffic, acceptable latency, availability requirements, and the operations consuming the most resources.
These estimates help reveal where scaling effort is actually needed.
Why Is One Application Server Not Enough?
A single server has limited CPU, memory, network capacity, and connection limits.
Vertical scaling can temporarily increase those resources by moving the application to a stronger machine. However, one machine eventually reaches practical or economic limits.
Horizontal scaling takes another approach by running multiple application instances.
Instead of sending all requests to one server, traffic is distributed across several servers. More instances can be introduced as demand increases.
This works especially well when application servers are relatively stateless. If important user session information exists only in one server's local memory, sending later requests to another instance can create problems.
Keeping appropriate state in shared systems can make application instances easier to add, replace, or remove.
How Does Load Balancing Help?
Once several application servers exist, incoming requests need to be distributed among them.
A load balancer sits in front of those servers and routes traffic toward suitable healthy instances.
If one server becomes unavailable, health checks can help prevent new traffic from continually being directed toward that failed instance. When demand increases, additional application instances can be placed behind the load-balancing layer.
However, load balancing solves only part of the problem.
If every application server sends every request to the same overloaded database, adding more servers may actually increase pressure on that database.
Scaling therefore requires examining the next bottleneck after each improvement.
Why Does Caching Matter at Large Scale?
Many high-traffic applications repeatedly request the same information.
In the social media example, popular public profiles or commonly accessed content may be requested thousands of times.
Querying the primary database for identical information on every request creates unnecessary work.
A cache stores frequently needed data in a faster-access layer. When the requested information exists there, the application can serve it without repeating the original database operation.
Caching can significantly reduce database pressure for suitable workloads, but it creates questions about expiration and invalidation.
If information changes in the database, designers need to decide how quickly cached copies should reflect the update. Data that changes constantly or requires the latest value may need different handling from relatively stable information.
How Can Static Content Be Served Efficiently?
Not every request needs to reach application servers.
Images, videos, stylesheets, JavaScript files, and other static assets can represent a significant portion of user traffic.
A Content Delivery Network, or CDN, can store suitable content at geographically distributed edge locations. Users can then retrieve cached content from an appropriate nearby location rather than repeatedly requesting it from the origin infrastructure.
This can reduce origin traffic and improve delivery latency, particularly for applications serving users across multiple geographic regions.
The application servers can then spend more of their capacity processing dynamic requests that actually require business logic.
What Happens When the Database Becomes the Bottleneck?
Database capacity often becomes one of the most important challenges as traffic grows.
The first response should not automatically be sharding.
Engineers can first examine slow queries, indexing, unnecessary database calls, connection usage, data models, and caching opportunities.
For read-heavy workloads, replication may provide additional read capacity when the database architecture and consistency requirements allow it.
At larger scales, sharding may become relevant when data size or workload can no longer be handled effectively by a single database instance.
Sharding distributes portions of the dataset across database nodes, but it also introduces routing, rebalancing, cross-shard queries, and distributed data-management challenges.
Database scaling should therefore evolve according to observed limitations.
How Does Asynchronous Processing Reduce Request Pressure?
Some tasks do not need to finish before a user receives a response.
Suppose a user uploads a post. The platform might need to update analytics, send notifications, process media, and perform other background operations.
Making the original request wait for every secondary task increases response time and creates more dependencies in the critical request path.
A message queue can separate suitable background work from the immediate operation.
The application produces a message, and background consumers process it independently.
This also provides a buffer during temporary traffic spikes. If work arrives faster than consumers can process it, pending messages can wait in the queue rather than forcing every task to execute simultaneously.
The architecture still needs retry handling, idempotency, monitoring, and capacity planning because a queue that grows indefinitely indicates another bottleneck.
How Does Rate Limiting Protect Capacity?
High traffic is not always evenly distributed or useful.
One client may accidentally make excessive API calls. Automated scripts may repeatedly request an expensive endpoint. Sudden bursts can consume resources that would otherwise serve many users.
Rate limiting controls how quickly requests are accepted according to a defined identity and policy.
For example, different rules might apply to authenticated users, API clients, or particularly expensive operations.
When designed carefully, rate limiting protects downstream services and provides controlled behavior when request volume exceeds expected boundaries.
It complements scaling rather than replacing it. Legitimate traffic from millions of different users still requires enough overall infrastructure.
Why Should Services Fail Gracefully?
Large distributed applications should expect individual components to fail.
Suppose the recommendation component of the social media platform becomes unavailable. The application might still be able to display a simpler feed rather than making the entire product unusable.
This principle is known as graceful degradation.
Timeouts are also important. If one service stops responding, other components should not necessarily wait indefinitely.
Retries may help with temporary failures, but uncontrolled retries can make an overloaded service even busier. Retry strategies therefore need appropriate limits and delays.
Reliability comes from designing for partial failure rather than assuming every component will always be healthy.
How Do Engineers Know What to Scale?
Observability provides the evidence needed to make scaling decisions.
Metrics can show request rates, latency, error rates, resource usage, database performance, cache effectiveness, and queue depth. Logs provide detailed information about events, while distributed tracing can help follow requests across multiple services.
Without these signals, engineers may add infrastructure without understanding the real bottleneck.
A slow application might have plenty of application-server capacity but suffer from one expensive database query. Adding more servers would not address the underlying cause.
Capacity planning should therefore be connected to measurement.
How Should Learners Design a Million-Request Architecture?
A System Design Course can approach this problem incrementally instead of beginning with dozens of distributed components.
Start with the social media application running on one server and database. Increase the expected traffic and identify the first limitation. Introduce horizontal scaling and load balancing when application capacity becomes insufficient.
Next, reduce repeated work through caching and move suitable static assets toward a CDN. Optimize database access before considering replication or sharding. Move non-critical background operations to asynchronous processing when appropriate.
Then examine rate limiting, failure handling, redundancy, and observability.
This sequence teaches why architecture evolves instead of encouraging learners to add components simply because large companies use them.
Frequently Asked Questions
1. Does Handling Millions of Requests Require Microservices?
No. Traffic volume alone does not require microservices. A well-designed monolith can scale significantly, while microservices introduce additional operational and distributed-system complexity.
2. Can Adding More Servers Solve Every High-Traffic Problem?
No. Other components such as databases, caches, queues, networks, or external services can remain bottlenecks even when application servers scale horizontally.
3. Why Are Traffic Estimates Important Before Designing the Architecture?
Traffic estimates help identify expected capacity, read and write patterns, peak demand, and likely bottlenecks. Without them, scaling decisions are largely assumptions.
4. Should Sharding Be Introduced as Soon as Traffic Becomes High?
Not necessarily. Query optimization, indexing, caching, replication, and other approaches may address database limitations with less complexity.
5. What Should Learners Study After High-Traffic System Design?
Useful next areas include high availability, multi-region architecture, autoscaling, distributed caching, database partitioning, event-driven systems, observability, and disaster recovery.
Conclusion
Handling millions of requests requires the workload to be distributed intelligently across an architecture. Load balancing and horizontal scaling expand application capacity, caching and CDNs reduce repeated work, database techniques address data-layer pressure, and asynchronous processing removes suitable background tasks from the immediate request path.
The most important principle is to scale according to evidence. Instead of adding every distributed-system component at once, designers can measure the system, identify its current bottleneck, and introduce the simplest architecture that addresses it. This creates systems that can grow while keeping their complexity connected to real requirements.
0 comments
Log in to leave a comment.
Be the first to comment.