
How Audio Annotation Services Improve the Accuracy of Speech Recognition Models
Speech Recognition Has Become a Critical Component of Modern AI Applications, Powering Virtual Assistants, Automated Customer Support, Transcription Platforms, In-Car Voice Systems, Healthcare Applications, and Conversational AI. However, the Performance of a Speech Recognition Model Depends on More Than Its Architecture. The Quality, Diversity, and Precision of Its Training Data Play a Major Role in Determining How Accurately It Understands Human Speech.
This is where audio annotation services become essential. By transforming raw speech recordings into structured, high-quality training data, annotation enables Automatic Speech Recognition (ASR) models to learn different accents, pronunciations, speaking styles, acoustic conditions, and linguistic patterns. High-quality ground-truth transcription and detailed audio labels can help reduce recognition errors and improve model robustness.
What Is Audio Annotation for Speech Recognition?
Audio annotation is the process of adding structured labels and metadata to audio recordings so that machine learning models can interpret and learn from speech signals.
For speech recognition systems, annotation can involve several layers, including:
Speech-to-text transcription
Timestamp and utterance segmentation
Phoneme annotation
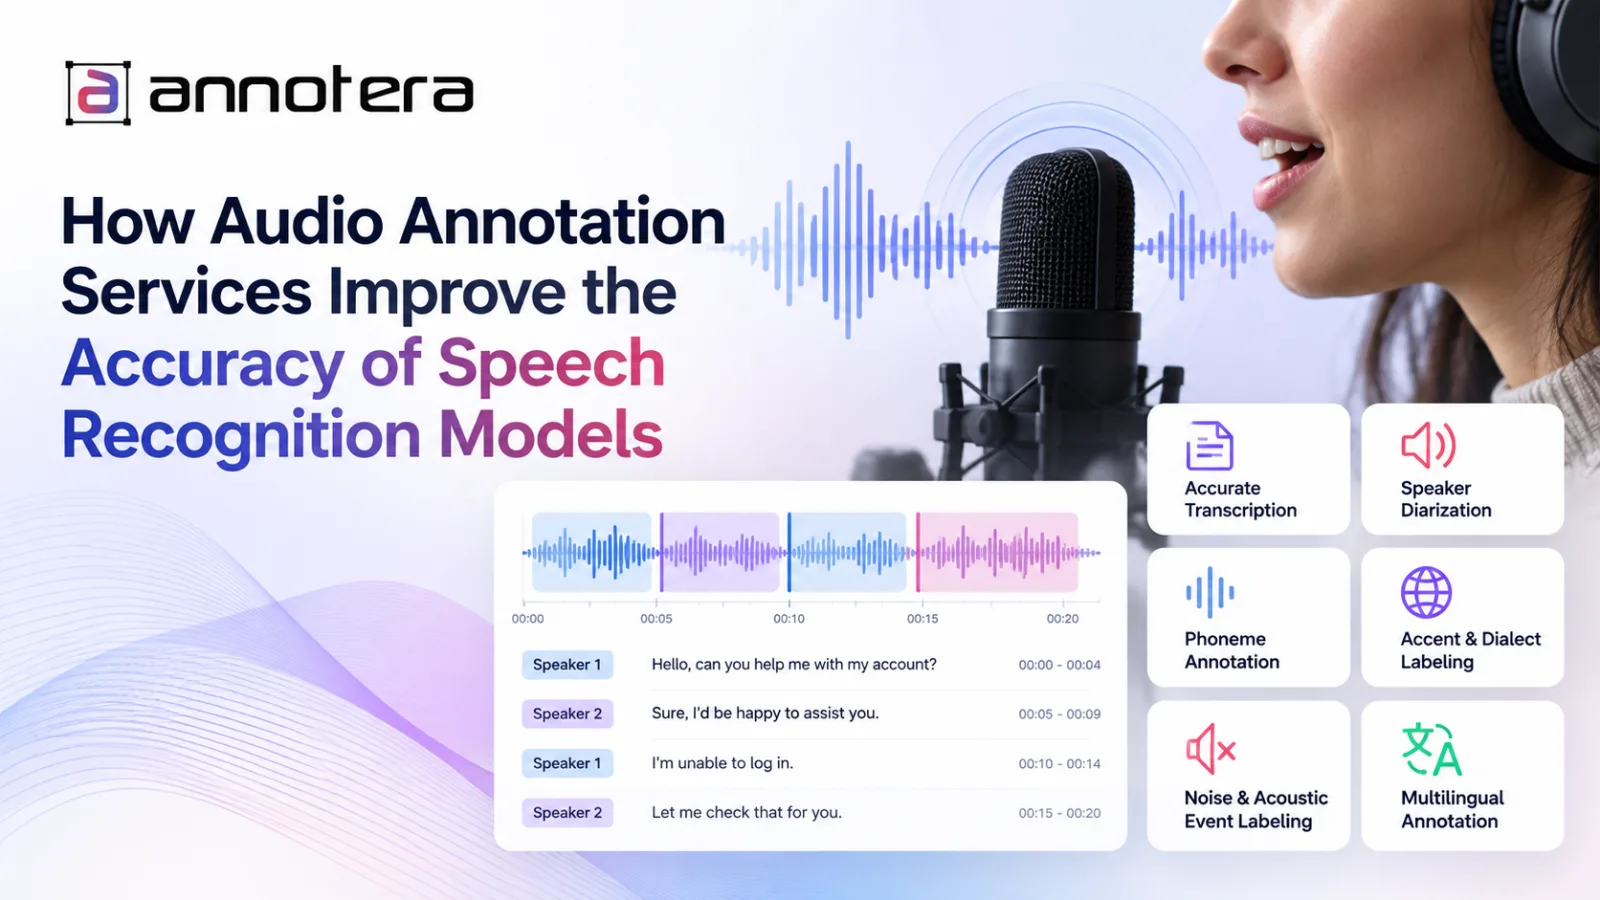
Speaker identification and diarization
Accent and dialect labeling
Silence and pause detection
Speech disfluency tagging
Noise and acoustic-event labeling
Language and code-switching identification
These annotations create a reliable representation of what is contained within an audio recording. Instead of simply receiving an audio file, the model receives structured information that connects acoustic signals with linguistic meaning.
Why Training Data Quality Matters for ASR Models
ASR models learn patterns from the examples included in their training datasets. If transcripts contain missing words, incorrect timestamps, inconsistent formatting, or misinterpreted speech, the model may learn inaccurate relationships between sound and language.
For example, consider an ASR dataset containing primarily clean studio recordings. A model trained on this data may perform well in controlled testing but struggle when users speak inside cars, offices, factories, restaurants, or crowded public spaces.
Similarly, a dataset dominated by one accent may not adequately represent speakers using regional dialects or different pronunciation patterns. Research and industry experience increasingly emphasize the importance of speaker, language, accent, and acoustic diversity when developing robust speech AI.
This makes accurate annotation a fundamental part of the ASR development pipeline rather than a simple data-preparation task.
1. Accurate Transcription Creates Reliable Ground Truth
Transcription converts spoken language into text that an ASR model can use as a reference.
High-quality transcripts need to accurately represent what the speaker said while following consistent project-specific guidelines. Depending on the application, teams may use verbatim transcripts that preserve hesitations and disfluencies or normalized transcripts designed for specific downstream applications.
Consistent transcription helps models establish stronger relationships between acoustic patterns and their corresponding words. Conversely, transcription errors can introduce incorrect training signals and contribute to higher Word Error Rates (WER).
2. Phoneme Annotation Helps Models Understand Pronunciation
Words can sound different depending on accent, speaking speed, regional pronunciation, or surrounding sounds.
Phoneme-level annotation breaks speech into smaller sound units, allowing models to learn detailed pronunciation patterns. This is particularly useful for systems that need to recognize diverse speakers or distinguish between acoustically similar sounds.
Phoneme annotation can also help identify pronunciation variations that conventional word-level transcription may overlook. High-quality phoneme labels therefore provide additional acoustic information for speech recognition models.
3. Accent and Dialect Annotation Improves Recognition Diversity
Human speech varies significantly across geographic regions. Speakers of the same language may use different pronunciations, vocabulary, intonation, and sentence structures.
If these variations are poorly represented in training data, ASR performance can vary across speaker groups. Regional audio annotation helps capture these differences as meaningful linguistic signals rather than treating them as noise.
Native and dialect-aware annotators can identify regional pronunciation patterns, vocabulary differences, and code-switching behavior, helping create datasets that better represent the environments where a model will ultimately operate.
4. Speaker Diarization Provides Valuable Context
In conversations involving multiple people, simply transcribing the words is not always sufficient. The model also needs to understand who said what.
Speaker diarization assigns speech segments to individual speakers. This is particularly valuable for:
Customer service conversations
Interviews
Meetings
Medical consultations
Podcasts
Call-center recordings
Multi-speaker conversational AI
Accurate speaker segmentation helps downstream systems associate each utterance with the correct participant and can improve the usability of conversational datasets.
5. Annotation Helps Models Handle Noisy Environments
Real-world speech rarely occurs in perfect acoustic conditions. Background conversations, traffic, machinery, music, wind, echoes, and low-quality microphones can all affect recognition.
Audio annotation can identify background noise, silence, overlapping speech, and other acoustic conditions. Training datasets can then intentionally include these scenarios, allowing models to learn how speech behaves outside controlled environments.
Annotera's audio data collection workflows, for example, emphasize varied acoustic environments because production speech systems need exposure to the conditions they are expected to handle.
6. Multilingual Annotation Supports Global Speech AI
Businesses operating internationally often need speech recognition systems capable of handling multiple languages and dialects.
Multilingual audio annotation helps identify language boundaries, regional pronunciation, code-switching, and language-specific speech characteristics. This is especially important in markets where speakers naturally switch between languages during conversations.
Language-specific annotation guidelines and native-speaker expertise can help maintain consistency across multilingual datasets rather than applying a single annotation methodology to every language.
Why Consider Audio Annotation Outsourcing Services?
Building an internal annotation operation requires trained linguists, project managers, quality-control teams, annotation tools, and scalable workforce capacity. These requirements can become challenging as datasets grow.
Audio annotation outsourcing services give AI companies access to specialized annotation teams without requiring them to build the entire operation internally.
Key advantages can include:
Faster dataset production
Access to trained linguistic resources
Multilingual annotation capabilities
Scalable workforce capacity
Structured quality assurance
Support for complex annotation taxonomies
Reduced operational burden for internal AI teams
Outsourcing can therefore allow machine learning teams to concentrate on model development while specialized teams manage data preparation and validation.
How Annotera Supports Speech Recognition Data Annotation
As an experienced audio annotation company, Annotera provides structured data services designed to support speech and conversational AI development.
Our capabilities can include:
Speech transcription
Phoneme annotation
Speaker diarization
Accent and dialect annotation
Multilingual audio annotation
Emotion and sentiment labeling
Audio event classification
Silence and pause identification
Human-in-the-loop validation
Multi-stage quality assurance
The goal is not simply to label more audio but to create training data that is consistent, representative, and aligned with the requirements of the target AI application.
Conclusion
Accurate speech recognition begins with accurate training data. From transcription and phoneme labeling to speaker diarization, accent recognition, and acoustic-event annotation, every layer of structured audio data can contribute to how effectively an ASR model learns human speech.
As speech AI expands into increasingly diverse real-world environments, organizations need datasets that represent different speakers, languages, accents, and acoustic conditions. High-quality annotation provides that foundation.
By working with specialized audio annotation outsourcing services, businesses can scale their data operations while maintaining structured workflows and quality controls. As an audio annotation company, Annotera helps AI teams transform raw audio into training-ready datasets designed to support more accurate and robust speech recognition systems.
0 comments
Log in to leave a comment.
Be the first to comment.