
How AI Is Turning Millions of Property Records Into Usable Data in Seconds
From county documents to structured intelligence, AI is reshaping how title and PropTech teams access, process, and use property data.
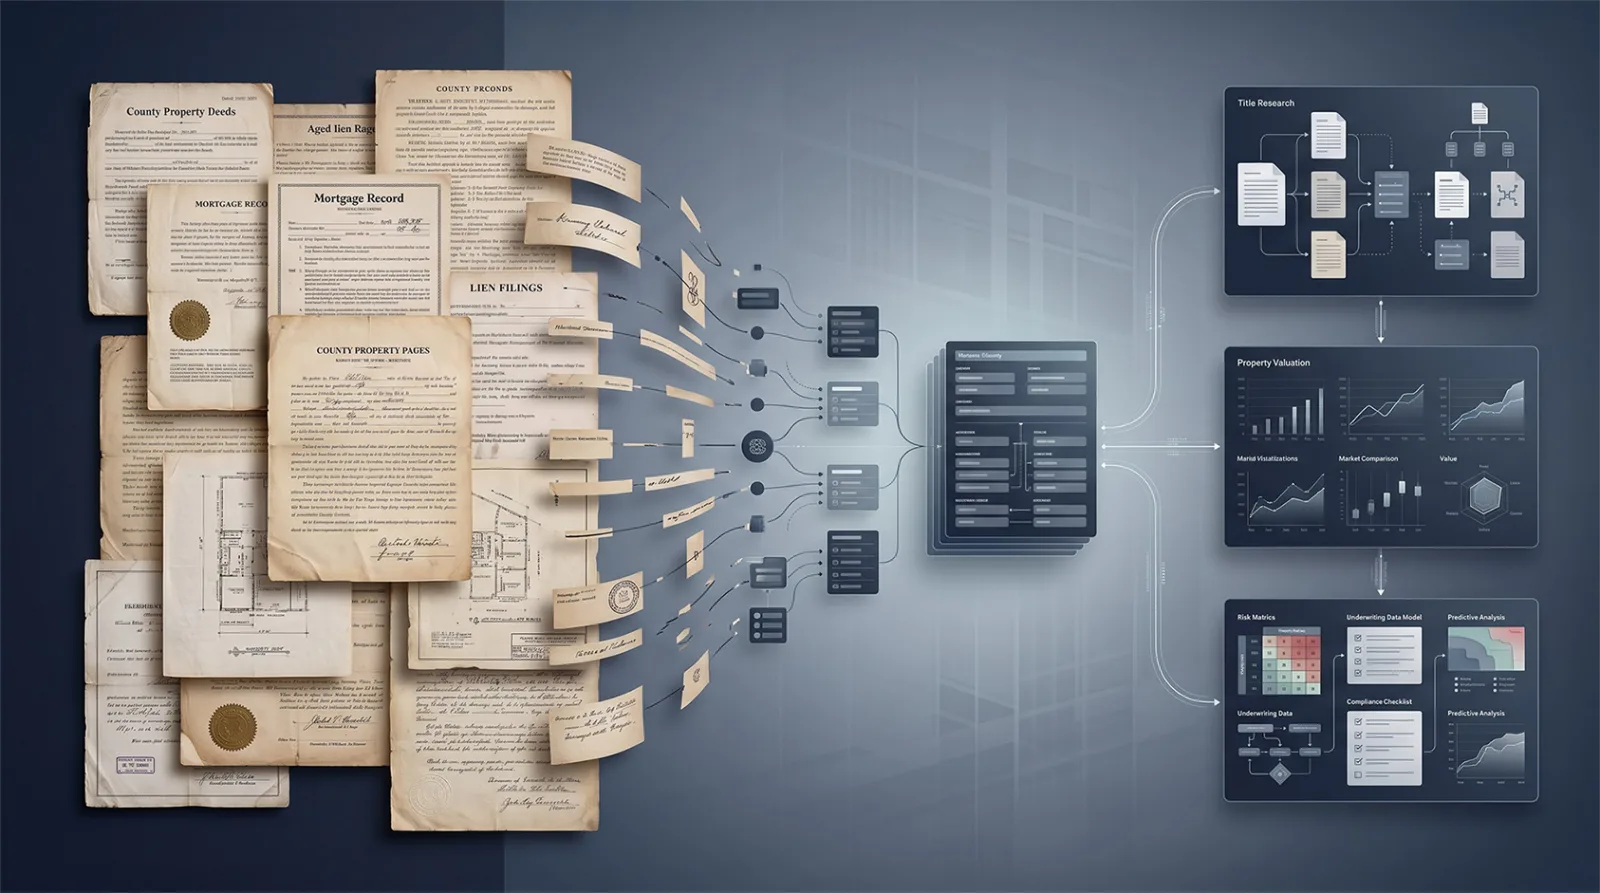
Across the U.S., property records live in thousands of county systems as scanned PDFs, images, and inconsistent indexes. For title teams, abstractors, and PropTech builders, that’s not just an IT problem. It’s a daily bottleneck.
AI is changing that. In seconds, it can turn messy, unstructured documents intoclean, structured data that plugs directly into title workflows and product backends.
The Bottleneck: Public Records That Aren’t Machine-Readable
There’s no shortage of property data. Deeds, mortgages, liens, assignments, releases. It’s all public records. But it’s rarely used in a form that’s easy to use.
· Records come with low-quality scans, handwritten notes, stamped corrections, and legacy indexes.
· Every county has its own format, naming conventions, and quirks.
· Some documents are clear. Others look like they were photocopied in 1987 and faxed twice.
For title, escrow, and abstracting teams, that means hours of manual reading, typing, and cross-checking. For PropTech companies, it means fragile data pipelines, inconsistent schemas, and models trained on noisy inputs.
The result? Slow turn times, high operating costs, and limited scalability.
What “Usable Data” Means for Title vs. PropTech
“Usable” does not just mean “digitized.” It means structured, standardized, and ready to plug into your systems. The exact shape depends on who you are.
For Title, Escrow, and Abstracting Teams
Usable data is what your production system expects:
· Vesting details: owner names, entity types, vesting language
· Legal descriptions: lot/block, metes & bounds, subdivision references
· Instrument type: warranty deed, quitclaim, mortgage, lien, assignment, release
· Recording metadata: date, book/page or instrument number
· Financials and parties: lien amounts, borrower/lender, beneficiary, maturity dates
That’s the kind of data that flows straight into title commitments, preliminary reports, curative worklists, and closing docs with far less manual keying.
For PropTech Product and Data Teams
Usable data is API-ready, normalized property intelligence:
· Normalized data fields for ownership, sales history, tax assessments, and liens
· A consistent schema across counties so your models do not break every time you add a new market
· Low-latency updates that power real-time search, alerts, valuations, and risk scores
In short: rows and JSON objects, not PDFs.
The AI Pipeline: From County PDF to Structured Fields
Turning raw records into usable data is not one model trick. It’s a multi-step pipeline designed for scale and accuracy.
Step 1: Ingesting Records Across Thousands of Counties
AI systems connect to:
· County recorder and assessor portals
· Bulk data vendors
· Document repositories and FTP feeds
They handle different file types (PDF, TIFF, images), access methods, and naming conventions so humans do not have to. For PropTech teams, this means resilient pipelines that can scale to millions of documents without constant manual fixes.
Step 2: OCR and Image Preprocessing
Older records are often blurry, skewed, or noisy. AI-powered OCR converts those images into machine-readable text, while preprocessing steps clean up:
· Skew and rotation
· Noise and speckles
· Low resolution and faint text
This is critical for title work, where decades-old deeds and handwritten indexes are still common.
Step 3: Classifying Document Types Automatically
Not every document is a deed. AI models classify each file into types like:
· Warranty deed, quitclaim deed
· Mortgage or deed of trust
· Tax lien, HOA lien, judgment
· Assignment, release, substitution of trustee
For title teams, that means automatic routing to the right workflow and faster exception identification. For PropTech products, it means clean tags for features like “recent lien activity” or “ownership change.”
Step 4: Extracting Entities and Mapping to Your Schema
This is where the real value shows up. NLP and LLM-based models pull structured fields from the text:
· Parties: grantor/grantee, borrower/lender, beneficiary
· Dates: recording, execution, maturity
· Amounts: loan size, lien amount, tax values
· Identifiers: APN/parcel ID, instrument number, book/page
· Legal descriptions and property addresses
Those fields are then mapped to:
· Title production systems (Qualia, SoftPro, ResWare, or custom TPS)
· PropTech data models and APIs with a canonical property record schema
Step 5: Confidence Scoring and Human Review
AI does not pretend to be perfect. It assigns confidence scores to each extracted field. Low-confidence or complex documents (multi-parcel instruments, corrections, modifications) get routed for human review.
The outcome:
· Title examiners focus on judgment calls and exceptions, not rote data entry.
· PropTech data teams get higher-quality training data and fewer bad records in production.
Step 6: Delivering Data via APIs and System Integrations
Finally, the structured data is delivered as JSON, CSV, or direct integrations into:
· Title software for order entry, commitment drafting, and policy issuance
· PropTech backends powering AVMs, search indexes, underwriting engines, and analytics dashboards
Per document, this happens in seconds. At scale, it’s millions of records turned into usable data without an army of data entry clerks.
How AI Streamlines Title and Abstracting Work
For title and abstracting leaders, this is not just “cool tech.” It’s operational leverage.
· Faster turn times: Order entry, search review, and commitment drafting move from hours to minutes.
· Less manual work: Far less copying and pasting from PDFs into production systems. Abstractors spend more time on analysis and curative work, less on transcription.
· Fewer errors: Automated extraction and validation reduce typos, missed liens, and incorrect vesting.
· Scalability: Volume spikes (refi waves, market surges) do not require linear headcount increases.
· Better examiner experience: AI drafts schedules and highlights likely exceptions. Humans make the final call.
A 20-person title team might see average file touch time drop by 30–40% while maintaining or improving accuracy. Abstractors can review 2–3x more chains of title per day because AI pre-populates key fields and flags changes.
AI's ability to handle difficult source documents has improved significantly. In a 2026 OCR benchmark, leading systems reached 95% accuracy on handwriting and 96% on printed text, although performance still varied considerably by document quality and format.
What Better Property Data Means for PropTech
For PropTech products and data leaders, property data quality is product quality.
· Better models: Cleaner; standardized records improve AVM accuracy, search relevance, and risk scoring.
· Faster shipping: Ready-to-use structured data shortens the path from idea to feature.
· More coverage: Expand into new counties and keep data fresh without massive manual ops.
· Lower costs: Less spend on manual data entry, vendor cleanup, and rework.
· AI-native products: Reliable data underpins LLM-powered property assistants, chat-based due diligence, and automated reports.
Your AVM’s performance is only as good as your underlying property and transaction data. AI-driven extraction turns county PDFs into API-ready records in near real time.
Where PropTech Teams Use Structured Property Data
· AVM and valuation platforms: Ingest sales, deeds, and tax data at scale to train and validate models.
· Property search and discovery tools: Enrich listings with ownership, tax, and lien data from public records.
· Investment and underwriting platforms: Generate automated due diligence packs with ownership history, recent instruments, lien flags, and assessment trends.
· Portfolio monitoring and risk products: Continuously scan for new liens, ownership changes, or assessment jumps across large portfolios.
When AI Needs a Human in the Loop
This is not magic, and it’s not perfect.
· Data quality varies by county. Some records are genuinely hard to parse.
· Complex legal instruments still need expert review.
· Blindly trusting automation without validation can introduce systematic errors.
· Public records use comes with regulatory and privacy considerations.
The best setups combine strong AI with human-in-the-loop review, continuous monitoring, and clear escalation paths for examiners and data teams.
More counties are digitizing and standardizing records, which means better inputs for AI. Tighter integrations are emerging between:
· AI in document extraction and title production workflows (commitments, policies, curative tools)
· Property data APIs and AI/LLM layers in PropTech products
What’s shifting is the baseline: AI-assisted examination in title and structured public-record data in PropTech are moving from “pilot projects” to core infrastructure.
As property records continue to move from paper and PDFs into structured, AI-ready data, the competitive advantage will go to the teams that can operationalize that data fastest, whether that’s in the title plant or the product backend.
0 comments
Log in to leave a comment.
Be the first to comment.