
CPU vs GPU: Which One Actually Powers Your AI Workload?
Understand the difference between data residency and data sovereignty in India, including the DPDP Act, CLOUD Act, compliance requirements, and how to choose a secure cloud
Most cpu vs gpu advice treats it as a speed contest. For AI workloads, it is mostly a memory contest, and that changes which one you should pay for.
The short version: your workload almost certainly uses both, the GPU does the heavy maths, and plenty of jobs people send to a GPU would run fine on a CPU. Here is how to tell which is which.
What Is the Real Difference Between a CPU and a GPU for AI?
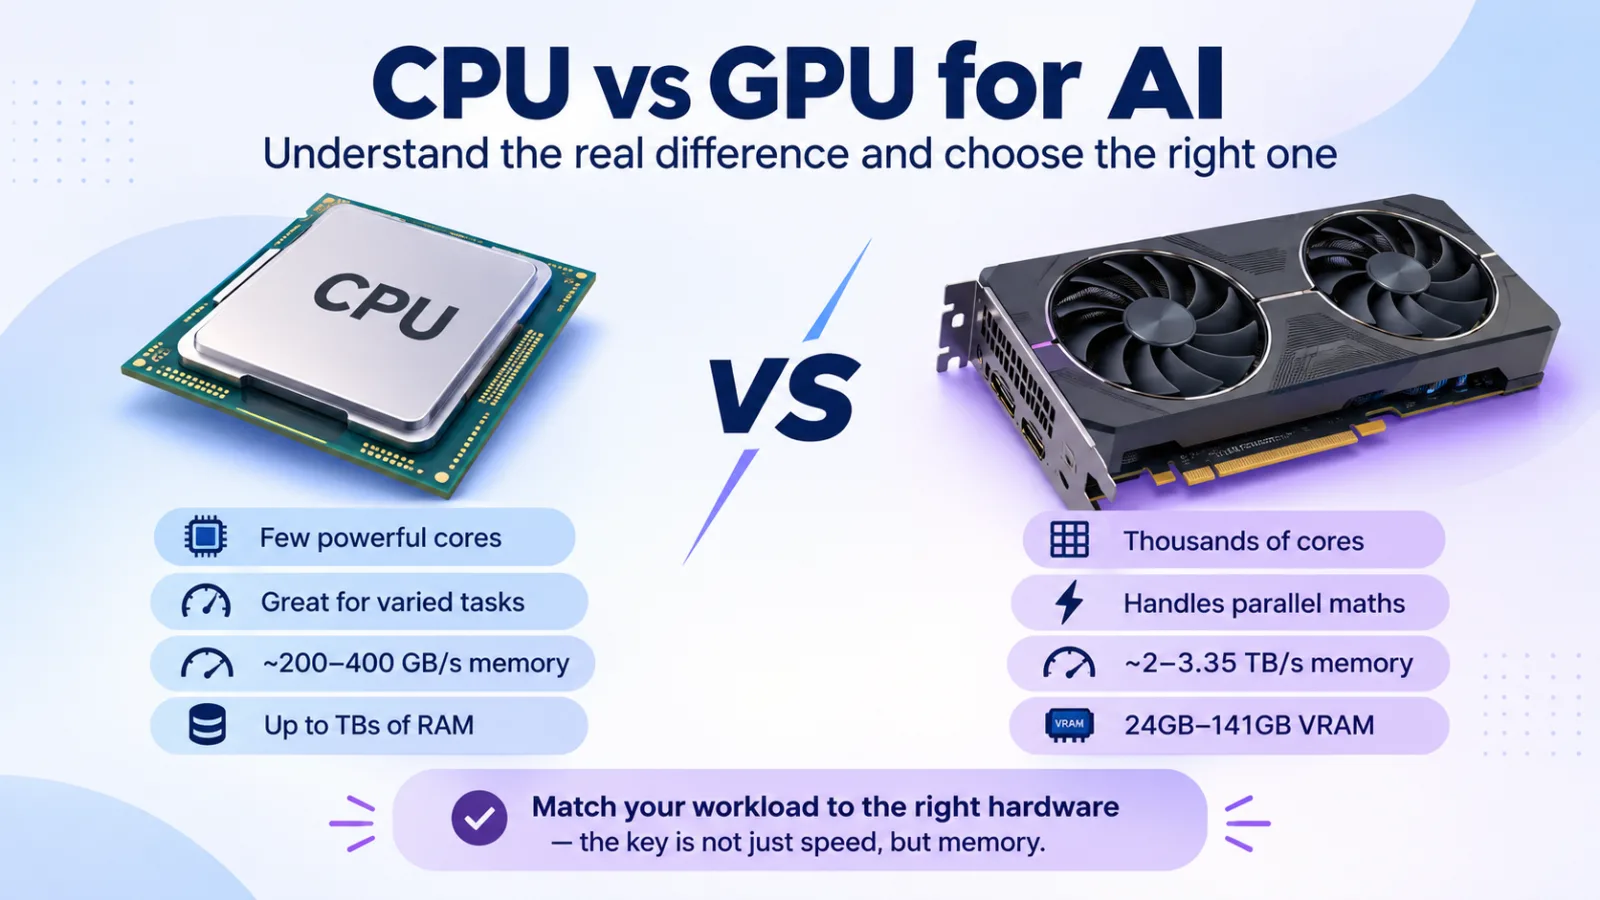
A CPU has a small number of powerful cores that handle varied, step-by-step tasks well. A GPU has thousands of simpler cores that do the same kind of maths on huge batches at once, which is exactly what neural networks need.
Why Does Memory Bandwidth Matter More Than Raw Speed?
Because generating each token means reading the whole model out of memory. That makes text generation limited by how fast memory can feed the chip, not by how fast the chip can calculate. A rough ceiling is memory bandwidth divided by the size of the model's weights.
Here is what that gives, assuming about 300 GB/s for a server CPU and 3,350 GB/s for an H100:
These are theoretical ceilings, and real speeds are lower. But the ratio is the point: the GPU is roughly ten times faster, mostly because its memory is.
When Is a CPU Enough for an AI Workload?
When the model is small, the outputs are short, the traffic is low or spiky, and you can live with a wait of around half a second to a second and a half for the first response. One 2026 decision framework puts the model range at 1B to 8B parameters, with outputs of about 150 tokens or fewer.
Workloads that sit comfortably on the CPU side:
Text embeddings, which use small models and can be batched
Reranking retrieved results
Classification and extraction, where the output is short
Speech to text, with a quantised build
Overnight batch summarisation, where nobody is waiting
AWS's own guidance for Kubernetes treats small quantised models of 1 to 8B as the default for CPU, and says CPU delivers the best cost per token for workloads that fit. If you choose CPUs, prioritise memory bandwidth over core count, since newer chips with more DDR5 memory channels run inference faster at the same clock speed.
Does Running on a CPU Lower the Quality of the Answers?
No. A 4-bit model produces the same output on a CPU as on a GPU. The difference is speed, not quality.
When Do You Actually Need a GPU?
When the job leans on bandwidth, concurrency or parallel maths.
Long contexts, around 16k tokens and above
Long generations, several hundred tokens per answer
High, sustained request rates, where batching keeps the GPU busy
Image, video and other multimodal work
Training and fine-tuning
The gap is large in practice. In one set of llama.cpp tests, GPU inference produced roughly 10 to 24 times more tokens per second than the same machine's CPU, depending on the model. A 70B model on a CPU generates at about reading-pause speed, which is fine for a batch job and painful for a chat.
What About Training and Fine-Tuning?
Use a GPU, essentially every time. Training needs about 16 bytes of memory per parameter for weights, gradients and optimizer states, plus activations, and it needs the parallel throughput to get through it in a reasonable time. The CPU's role is the supporting work: preparing data, loading it and orchestrating the job.
Do Most AI Workloads Use Both?
Yes, and this is the part most comparisons skip. A real pipeline is a relay:
The CPU cleans and tokenises the input, runs retrieval and calls any tools
The GPU runs the model
The CPU parses the result, applies business logic and sends the response
For agent workloads the CPU's share grows. Sizing guides suggest 4 to 8 vCPUs per GPU for plain inference and 8 to 24 for agentic pipelines. If the CPU side is too small, the GPU sits waiting, and you pay GPU rates for that waiting.
How Do You Decide Which One Your Workload Needs?
Match the job to the table.
There is also a middle ground. A small, low-cost GPU such as the L4 sits between the two for models that are too slow on a CPU but do not need a large card.
What Does a Sensible Split Look Like in Practice?
Here is an illustrative case. Picture a support assistant for a small online shop. Embedding the help articles and reranking search results runs on a couple of CPU cores. The model that writes answers is an 8B model that must reply within a couple of seconds to several people at once, so it goes on a single small GPU.
The nightly job that summarises the day's tickets runs on a CPU, since nobody is waiting for it. Three jobs, two kinds of chip, and the GPU is paid for only where it earns its keep.
What Mistakes Do People Make When Choosing?
Renting a GPU for embeddings or a small classifier, and paying GPU rates for a job a CPU handles
Comparing CPUs by core count when memory bandwidth is what limits them
Forgetting the CPU on a GPU node, then wondering why the GPU is idle
Expecting a 70B model to feel interactive on a CPU
Assuming a GPU is always cheaper per token, when at low utilisation it often is not
Conclusion
Ask three questions: how big is the model, how long are the inputs and outputs, and how many people are asking at once. Small, short and quiet points to a CPU. Large, long and busy points to a GPU. And whichever you choose, make sure the other half of the pipeline is not starving it.
Frequently Asked Questions
Can I run an LLM without a GPU?
Yes. Small quantised models run through tools like llama.cpp. A 7B or 8B model at 4-bit is usable on a good CPU, though it feels slow for live chat.
Is a GPU always cheaper per token?
No. A GPU pays off at high, sustained utilisation. At low or spiky traffic, a CPU can be cheaper because you are not paying for a card that sits idle.
Do I need a GPU for RAG?
Not for the retrieval half. Embeddings and reranking run well on CPUs. The generation step over a long retrieved context is where a GPU earns its keep.
0 comments
Log in to leave a comment.
Be the first to comment.