
Can Non-IT Students Start Learning With a Data Science Course in Telugu?
Data Science Course in Telugu
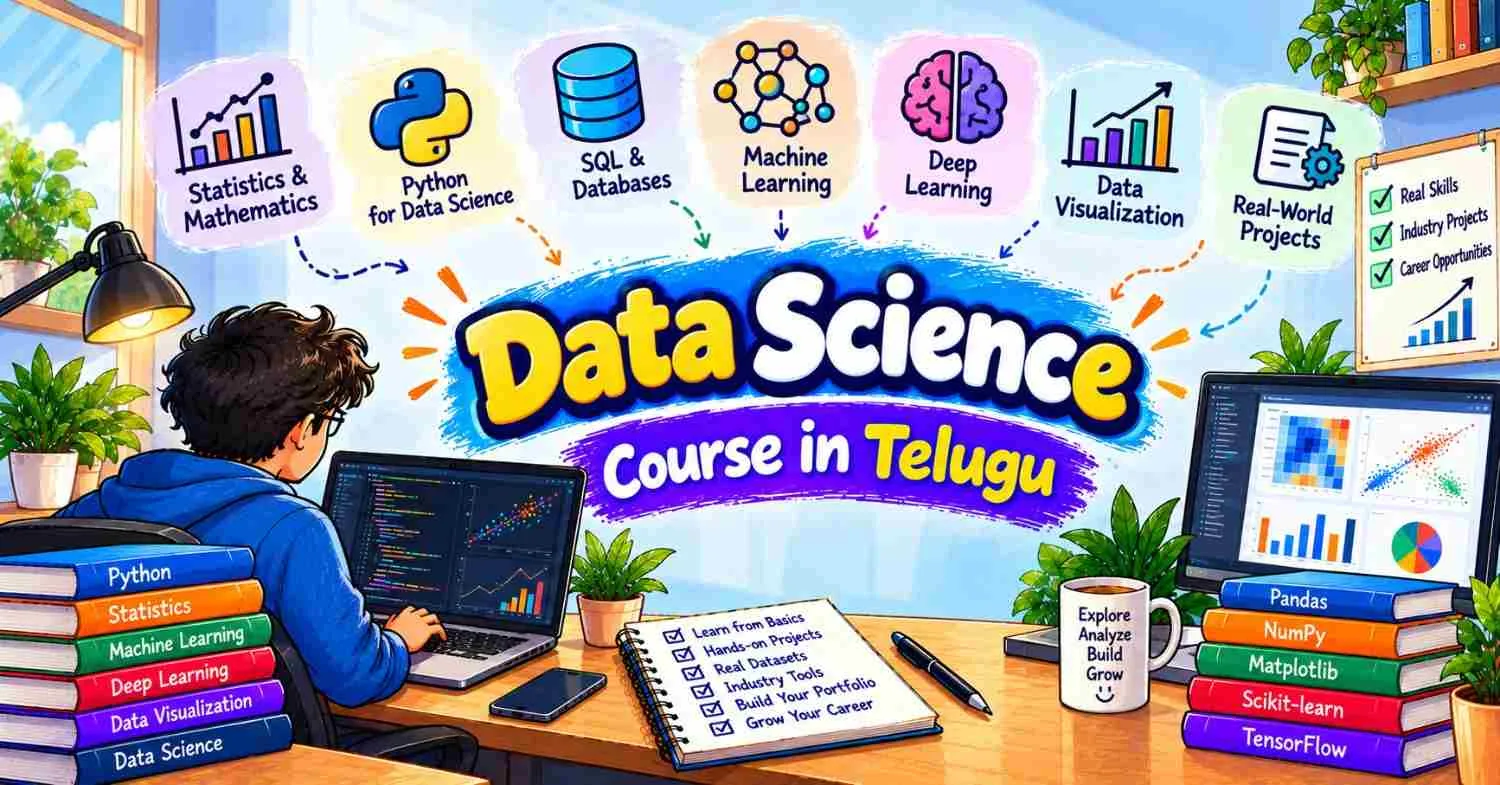
Yes, students from non-IT backgrounds can start learning data science, but they need to build the required foundations gradually. A computer science degree is not a compulsory starting point for understanding data, statistics, Python, SQL, visualization, or basic machine learning. A Data Science Course In Telugu can be approached by learners from commerce, management, mathematics, life sciences, mechanical engineering, civil engineering, and other backgrounds when concepts are learned in a logical sequence.
Is an IT Background Necessary for Data Science?
Data science combines several areas rather than depending entirely on traditional software development knowledge. Programming is one part, but learners also work with data interpretation, statistics, problem definition, visualization, and analytical reasoning.
A commerce student, for example, may already be familiar with percentages, averages, financial information, and spreadsheets. A mechanical engineering student may have experience interpreting measurements and numerical relationships. A management student may understand business processes and performance indicators.
These existing abilities can provide useful context, although learners still need to develop technical skills required for working with data.
The starting point may differ from one person to another, but the core learning path can remain similar.
What Should a Non-IT Beginner Learn First?
Beginners should first understand what data represents before moving directly into machine learning algorithms.
Concepts such as rows, columns, variables, numerical data, categorical data, missing values, and datasets provide an important foundation.
For example, imagine a dataset from a supermarket containing transaction date, store, product category, quantity, discount, and sales amount. Before writing code, a learner should understand what one row represents and what questions could reasonably be answered from those columns.
This habit of understanding the data before choosing a tool becomes increasingly important as projects become more complex.
How Much Programming Does a Beginner Need?
Programming can initially appear difficult for learners who have never written code, but data science does not require beginners to start with advanced software development.
Python fundamentals can be learned progressively.
A beginner first needs to become comfortable with variables, data types, conditions, loops, functions, and basic data structures. These concepts provide enough foundation to begin understanding how Python can manipulate datasets.
Later, libraries such as Pandas and NumPy can be introduced for data-related operations.
The objective should be to understand what the code is doing rather than memorize long programs. If a learner can explain why a particular operation is required, adapting the syntax becomes easier with practice.
Do Non-IT Learners Need Advanced Mathematics?
Advanced mathematics is not required before beginning every data science topic.
However, mathematical and statistical understanding becomes important as learners progress.
A beginner can start with familiar concepts such as averages, percentages, ratios, distributions, and variation. From there, concepts such as variance, standard deviation, probability, correlation, sampling, and statistical inference can be introduced.
Machine learning may later require additional mathematical intuition depending on how deeply the learner studies particular algorithms.
The useful approach is to learn mathematics in context. Understanding why a statistical concept is needed for a data problem is often more meaningful than studying formulas without an application.
Why Is Statistics Important for Non-IT Students?
Statistics helps learners reason about data rather than simply produce calculations.
Suppose a supermarket's average daily sales increased after a change in store layout. The average alone does not explain whether the increase occurred consistently, whether a few unusually busy days influenced the result, or whether other factors were involved.
Statistical reasoning encourages learners to investigate variation, distributions, samples, relationships, and uncertainty.
This is particularly valuable for non-IT students because statistics provides a bridge between familiar real-world questions and more technical data science methods.
Where Does SQL Fit Into the Learning Path?
Many practical datasets are stored in databases rather than individual spreadsheet files.
SQL allows learners to retrieve and organize information from structured databases.
A beginner can gradually learn how to select required columns, filter records, sort results, group observations, calculate summaries, and combine related tables.
For example, customer information may exist in one table while transaction records exist in another. SQL can connect those datasets through appropriate relationships.
Understanding SQL also teaches learners to think about how structured information is stored and retrieved before it reaches Python or a machine learning workflow.
How Does Data Cleaning Build Practical Skills?
Real data is rarely perfect.
A supermarket dataset might contain missing product categories, duplicate transactions, inconsistent date formats, or incorrect sales values.
Data cleaning teaches learners to identify these problems and decide how they should be handled.
This is an area where analytical thinking matters as much as technical knowledge.
Deleting every incomplete record, for example, may remove useful information. Filling every missing value with the same number can also distort the dataset.
Learners need to understand why information is missing and how a cleaning decision might influence later analysis.
Why Should Beginners Learn Data Visualization?
Visualization provides a relatively accessible way for non-IT learners to begin interpreting datasets.
Charts can reveal patterns that are difficult to identify from hundreds or thousands of rows.
A time-series chart might reveal seasonal sales changes, while a histogram can show how numerical values are distributed. A scatter plot may help investigate whether two numerical variables appear related.
Visualization also teaches an important communication skill.
A technically correct analysis has limited value if its findings cannot be explained clearly to another person.
Learners should therefore understand not only how to create charts but also how to select visualizations that accurately represent the question.
When Should Machine Learning Be Introduced?
Machine learning becomes easier to understand after learners are comfortable with basic data handling, Python, statistics, and exploratory analysis.
Starting directly with algorithms can lead to a situation where a learner knows how to execute a model but cannot explain the dataset or evaluate the result.
A more useful progression is to understand supervised and unsupervised learning before studying individual models.
Regression can introduce numerical prediction. Classification can introduce categorical prediction, while clustering can demonstrate how patterns may be explored without predefined target labels.
Decision trees and other models can then be studied in relation to specific problems rather than as isolated algorithms.
Can Domain Knowledge Help Non-IT Learners?
Yes. Domain understanding can become a useful part of data science reasoning.
Consider an agriculture graduate working with crop-related data. Knowledge of seasons, soil conditions, rainfall, and farming practices may help that learner recognize relationships or questionable values that someone unfamiliar with the domain could overlook.
Similarly, a finance graduate may better understand financial variables, while a healthcare learner may recognize the meaning of clinical or operational measurements.
Technical skills help process the data, but domain knowledge helps frame sensible questions and interpret results within context.
What Should a First Non-IT Data Science Project Look Like?
A first project should be understandable rather than unnecessarily complex.
In a Data Science Course In Telugu, a non-IT beginner could start with a public retail inventory dataset containing product categories, stock levels, sales quantities, dates, and store information.
The learner could inspect the dataset, identify quality problems, clean relevant fields, calculate descriptive statistics, and visualize stock and sales patterns.
Once these foundations are comfortable, the project could be extended into a clearly defined predictive problem if the available data supports one.
This progression allows the learner to understand each stage instead of jumping immediately to a complicated model.
How Can Non-IT Learners Avoid Feeling Overwhelmed?
Trying to learn Python, SQL, statistics, machine learning, deep learning, NLP, and Generative AI simultaneously can make the field appear more difficult than necessary.
Learning one layer at a time creates a clearer progression.
The focus should remain on understanding the purpose of each concept. Python helps manipulate information, SQL retrieves structured data, statistics helps interpret evidence, visualization reveals patterns, and machine learning helps model particular relationships.
Once these connections become clear, the tools begin to feel like parts of one workflow rather than unrelated technologies.
Frequently Asked Questions
1. Can a Commerce Student Learn Data Science?
Yes. Commerce students can begin with data fundamentals, statistics, Python, SQL, and analytical projects before progressing toward machine learning.
2. Does a non-IT Student Need to Learn Software Development Before Data Science?
No. Basic programming ability is important, but beginners do not need to master full software development before starting data analysis and introductory modeling.
3. How Should Someone With Weak Mathematics Begin?
Starting with arithmetic, percentages, averages, basic algebra, and descriptive statistics can build the foundation needed for more advanced statistical and machine learning concepts.
4. Can Previous Domain Knowledge Be Used in a Data Science Project?
Yes. Domain knowledge can help learners choose meaningful variables, identify unrealistic values, frame relevant questions, and interpret findings more carefully.
5. Should a non-IT Beginner Start Directly With Deep Learning?
Usually, building foundations in Python, data preparation, statistics, exploratory analysis, and basic machine learning first makes deep learning concepts easier to understand.
Conclusion
A non-IT background does not prevent someone from beginning data science. The more important requirement is building the foundations in the right order and understanding why each skill is used.
Starting with data fundamentals, progressing through Python, SQL, statistics, cleaning, and visualization, and then moving into machine learning gives beginners a structured way to develop their knowledge. Previous academic or professional domain knowledge can also become valuable when learners begin working with real datasets and interpreting results within practical contexts.
0 comments
Log in to leave a comment.
Be the first to comment.