
Before You Hire a Data Scientist, Ask Your Organization These Questions
The decision to hire a data scientist is usually driven by a recognition that data should be doing more for the organization than it currently is. That recognition is correct. What is less often examined is whether the organization is actually ready to make a data science hire successful — and readiness here means something more specific than having a job description and a budget.
The questions below are not interview questions for candidates. They are readiness questions for the organization. Working through them before initiating a search prevents the most common and expensive form of data science hiring failure: placing the right person in an environment that cannot support them.
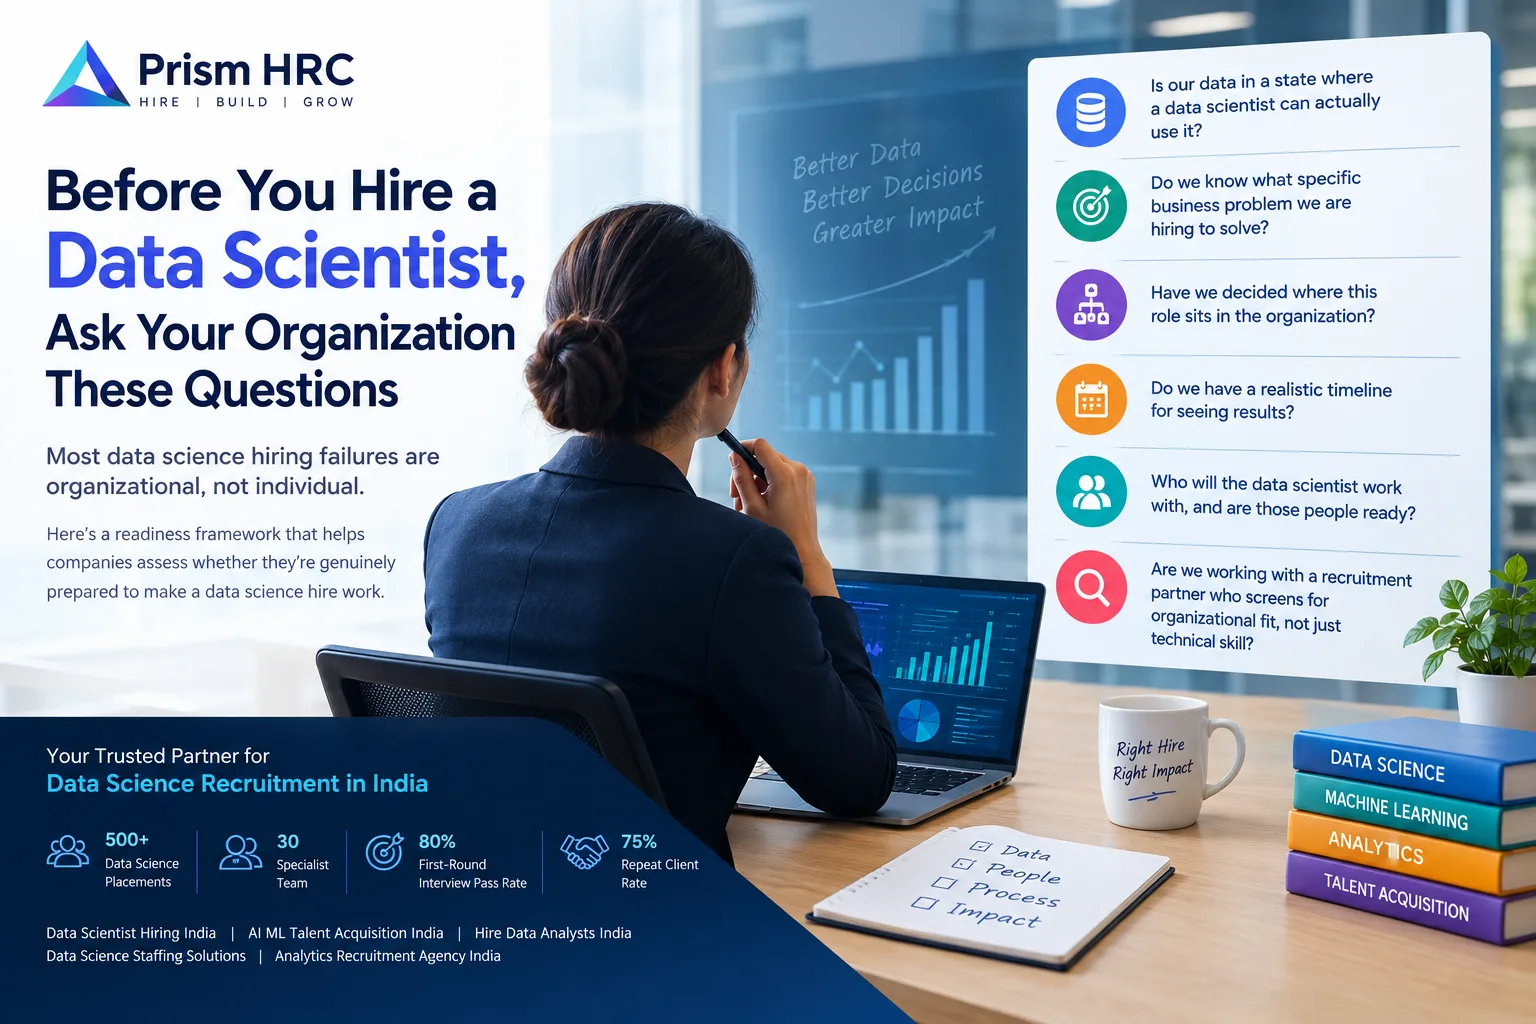
Is Our Data in a State Where a Data Scientist Can Actually Use It?
This is the foundational question, and the honest answer is "no" for more organizations than would like to admit it. A data scientist's core work — building models, identifying patterns, generating predictions — requires data that is accessible, reasonably clean, consistently structured, and documented well enough to understand what it represents.
If the organization's data lives in siloed systems with no integration layer, in spreadsheets maintained by different teams with inconsistent field definitions, or in databases that require significant manual effort to query — the first six months of any data scientist hire will be infrastructure work, not data science. That is not a wrong outcome if it is planned for and communicated. It is a very wrong outcome if the hire was expected to be generating models and insights immediately.
A useful internal test: can someone currently in the organization pull a clean, reliable dataset for a specific business question within a day? If the answer is no, the data engineering problem should be addressed before or alongside the data science hire — not after.
Do We Know What Specific Business Problem We Are Hiring to Solve?
"We want to do more with our data" is not a scope. The data scientist who joins and is given this brief will spend their first two months in discovery conversations trying to understand what the organization actually wants, often with stakeholders who have not aligned on the answer themselves.
The clearest data science hires are made against specific, defined problem statements. Not "improve customer retention" — but "build a model that identifies customers with a greater than 60% probability of churning within 90 days, using transaction history and engagement data, so that the CRM team can prioritize their outreach." That level of specificity allows the hiring process to evaluate whether a candidate has relevant experience, and it allows the data scientist, once hired, to begin work with direction rather than drift.
If this level of problem definition does not yet exist, the most useful pre-hiring step is a structured internal conversation between the business and technology stakeholders to produce it — before the search begins.
Have We Decided Where This Role Sits in the Organization?
A data scientist who reports to the CTO operates differently from one who reports to the Head of Marketing, the Chief Analytics Officer, or directly to the CEO. The reporting line determines which problems they work on, whose priorities they serve, how much access they have to relevant stakeholders, and how their output is evaluated and acted upon.
Organizations that have not made this decision before hiring find that the data scientist becomes a resource that everyone wants access to and no one is accountable for — pulled in multiple directions, producing work that is interesting but not acted on, and eventually leaving because the lack of structural clarity makes meaningful impact impossible.
Do We Have a Realistic Timeline for Seeing Results?
Data science investments typically take six to twelve months before they produce business-grade outputs. The first month or two is environment understanding and data exploration. The next two to three months is model development and initial validation. Productionizing, testing against real outcomes, and iterating based on results takes further time after that.
Organizations that expect a data scientist to present a production-ready predictive model with measured business impact within the first three months almost always end up disappointed — not because the hire was wrong, but because the expectation was wrong.
Setting realistic timelines internally, and communicating them to the hire as part of onboarding, prevents the misalignment that leads to premature conclusions about whether the investment is working.
Who Will the Data Scientist Work With, and Are Those People Ready?
Data science does not operate in isolation. A churn model that is not integrated into the CRM workflow produces insights, not outcomes. A pricing optimization algorithm that the product team does not trust produces reports, not decisions. An anomaly detection system that engineering does not deploy produces analysis, not protection.
Every data science output requires a downstream human action for its value to be realized. Before hiring, the organization should identify who those downstream stakeholders are, confirm they understand what data science can and cannot do, and establish that there is genuine appetite to act on what the work produces.
A data scientist placed in an organization where stakeholders are skeptical of data-driven decisions, or where there is no process for translating model outputs into operational action, will eventually stop investing in the quality of their work — because the signal they receive is that quality does not matter.
Are We Working With a Recruitment Partner Who Screens for Organizational Fit, Not Just Technical Skill?
The candidate side of the equation is only half the picture. A strong data science hire requires someone who can navigate the specific organizational environment they are joining — its maturity level, its data infrastructure, its stakeholder dynamics, and its realistic timelines.
Prism HRC's approach as a specialist data science recruitment agency is to understand the organizational context as thoroughly as the role requirements before beginning the search. With 500+ data science placements, a team of 30 specialists, an 80% first-round interview pass rate, and a 75% repeat client rate, the outcomes they consistently produce reflect screening that goes beyond technical evaluation — assessing whether candidates are equipped to thrive in the specific environment they would be entering, not just capable of performing the generic job description.
An organization that has worked through these questions — that has reasonably clean data infrastructure, a specific problem scope, a clear reporting structure, realistic timelines, and engaged stakeholders — will get significantly more value from a data science hire than one that treats these as details to be sorted out after the person joins.
The preparation is not complex. It takes a few focused internal conversations and some honest self-assessment. But it changes the probability of the hire succeeding from uncertain to high — and that difference is worth the time it takes.
A data science hire placed in an unprepared organization is not a data science failure — it is an organizational planning failure that was decided before the first interview.
Author Bio
Nikhil Vaidya is the CEO of Prism HRC, a leading recruitment services company in India. Nikhil's expertise in talent acquisition and has been instrumental in connecting hundreds of top-notch clients with exceptional IT talent over the last 15 years.
0 comments
Log in to leave a comment.
Be the first to comment.