
Azure Data Engineer Course in Telugu: Learn SQL for Cloud Data Engineering
Introduction
SQL remains one of the most important skills in data engineering because structured data is still central to reporting, analytics, warehousing, and business applications. Even when data is stored in cloud platforms or data lakes, engineers often use SQL to inspect datasets, filter records, join tables, aggregate information, validate transformations, and prepare data for downstream consumption.
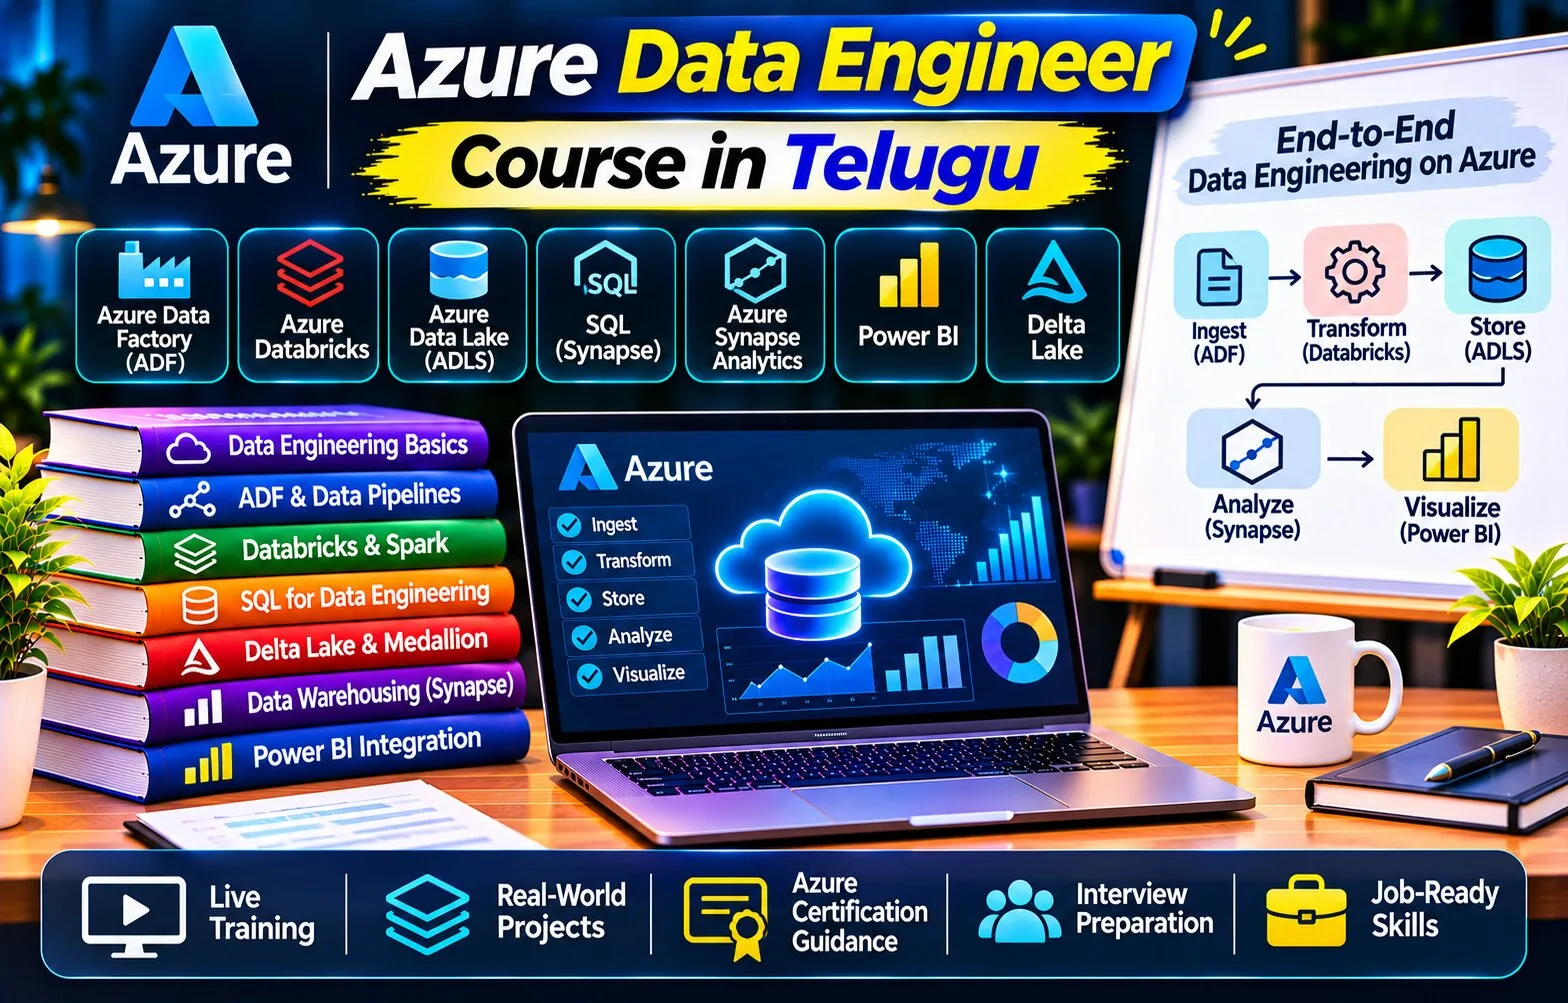
An Azure Data Engineer Course in Telugu can help beginners understand how SQL fits into cloud data engineering on Microsoft Azure. Learners should know more than basic SELECT statements. They should understand joins, grouping, window functions, common table expressions, data quality checks, incremental logic, and query performance. The goal is to use SQL as a practical engineering tool for building and validating reliable data workflows.
SQL in Data Engineering
A data engineer may use SQL for:
data profiling
validation
transformation
aggregation
warehouse loading
report preparation
Start With SELECT
The SELECT statement retrieves data.
A basic query may return:
OrderId
CustomerId
Revenue
OrderDate
Beginners should become comfortable with:
selecting specific columns
renaming columns
sorting output
limiting rows
Avoid selecting every column when only a few are required.
Filtering With WHERE
The WHERE clause restricts rows.
Examples include:
completed orders only
one date range
specific region
positive quantities
For example, a pipeline validation query may return records where:
Quantity <= 0
This makes SQL useful not only for reporting but also for identifying data-quality problems.
Aggregation
Analytics workloads frequently require summaries.
Common aggregate functions include:
SUM
COUNT
AVG
MIN
MAX
Suppose a table contains transaction-level sales.
A query can calculate:
total revenue by region
order count by month
average order value by customer segment
GROUP BY is central to these analytical queries.
Joins
Data engineering often requires information from multiple tables.
Common join types include:
INNER JOIN
LEFT JOIN
RIGHT JOIN
FULL OUTER JOIN
Suppose orders contain ProductId while product names are stored separately.
A join can combine them.
The engineer must understand whether unmatched records should remain.
A careless join can change row counts and produce incorrect business totals.
Validate Joins
Before accepting a join result, compare:
source row count
output row count
duplicate keys
unmatched records
For example, joining a transaction table to a dimension containing duplicate ProductId values may multiply rows unexpectedly.
This can inflate revenue and other metrics.
NULL Handling
NULL represents missing or unknown information.
It should not automatically be treated as zero or an empty string.
SQL provides functions and conditions for working with NULL values.
The correct handling depends on business meaning.
For example:
missing discount may mean no discount
or it may mean the source failed to provide data
Those cases should not be assumed to be identical.
Common Table Expressions
Common Table Expressions, or CTEs, help organize complex queries into readable steps.
A query may first calculate:
monthly sales
then rank regions
then select the top performers
Breaking logic into named sections can make transformations easier to maintain than deeply nested queries.
Window Functions
Window functions are valuable for analytical processing.
They can support tasks such as:
ranking
running totals
previous-row comparison
deduplication
Examples include:
ROW_NUMBER
RANK
SUM over a window
LAG
A common data-engineering use case is assigning ROW_NUMBER within each business key and keeping the newest record.
Deduplication With SQL
Suppose multiple rows exist for the same CustomerId.
The requirement is to keep the most recently updated record.
A window function can:
partition by CustomerId
order by UpdatedTime descending
assign row numbers
keep row number 1
Incremental Loading
SQL can help identify new or changed data.
A pipeline may filter records where:
UpdatedTime > previous watermark
This prevents processing the complete table every run.
Incremental logic must be designed carefully to avoid:
missing records
duplicate loads
incorrect boundary conditions
The watermark should be stored and updated reliably.
Fact and Dimension Queries
Cloud data warehouses often use fact and dimension models.
A fact table may contain:
sales transactions
A dimension table may contain:
customer
product
date
SQL joins allow analysts to combine measurable facts with descriptive attributes.
SQL and Azure Platforms
SQL can appear across multiple Azure data services.
Depending on the architecture, engineers may use SQL to:
query relational databases
explore lake data
work with warehouse tables
validate pipeline results
The syntax and capabilities may vary between engines, so queries should be tested in the actual platform.
Query Performance
A query can be correct and still perform poorly.
Performance considerations include:
amount of data scanned
join size
filter placement
partitioning
table design
selected columns
Data engineers should avoid assuming that cloud compute removes the need for efficient query design.
Data Quality Checks With SQL
SQL can validate pipeline outputs.
Examples include:
count rows
find duplicate IDs
check null percentages
identify invalid dates
compare totals before and after transformation
These checks can be automated as part of pipeline monitoring.
A technically successful load should not be considered complete if the resulting data is incorrect.
Practical Exercise
Create three tables:
Orders
Customers
Products
Write queries to:
join orders with customer and product information
calculate monthly revenue
find duplicate OrderIds
identify null CustomerIds
rank products by revenue
select only records changed after a watermark
For each query, explain its business purpose instead of focusing only on syntax.
Why Telugu-Based Learning Can Help
Cloud SQL introduces terms such as join, aggregate, CTE, window function, watermark, fact table, dimension table, partition, and query optimization.
An Azure Data Engineer Course in Telugu can explain these concepts in Telugu while preserving the English terminology learners will encounter in Azure analytics services, SQL editors, documentation, projects, and interviews.
Frequently Asked Questions
Is SQL Still Important for Cloud Data Engineers?
Yes. SQL remains used for transformation, validation, querying, warehousing, and analytics.
Why Are Window Functions Useful?
They help with ranking, running calculations, comparisons between rows, and deduplication without collapsing all detail.
What Is a Watermark in Incremental Loading?
A watermark is a tracked value, such as a timestamp or ID, used to identify data that is new or changed since the previous run.
Should Data Engineers Always Use SELECT *?
No. Selecting only required columns usually makes queries clearer and can reduce unnecessary data processing.
Conclusion
SQL is a foundation skill for cloud data engineering because it connects raw data with transformation, validation, warehousing, and analytics.
Joins, aggregations, NULL handling, CTEs, window functions, deduplication, incremental loading, and performance awareness allow engineers to solve data problems beyond basic querying. SQL is especially valuable when it is used together with data-quality checks and clear business definitions.
Learners who practice SQL on realistic Azure data workflows can build stronger pipelines and troubleshoot data issues with greater confidence.
0 comments
Log in to leave a comment.
Be the first to comment.